Jev pricing: what a decision actually costs
Input-only pricing, because there is no output to pay for. The sticker price is the boring half — the useful question is what the same decision costs you today, which is what the calculator below is for.
How much does one Jev decision cost?
Short answer: Jev pricing is one rate card, $0.042 per 1M input tokens (output free). A real one-Choice call we ran cost $0.0000144 — about 20× below the ~$0.0004/decision figure that circulates from vendor materials, because a typical state is hundreds of tokens, not thousands.
Those measured dollars are what the API itself reported on live calls (2026-09-18), not arithmetic guessed from the rate card. Cost scales only with input tokens (state + questions), so put every question into one call: questions share one state and run in parallel; three separate calls pay for the state three times.
There is no free tier documented at launch. TypeSafe has said it cannot prove the price is not subsidised — model unit economics with headroom.
| Rate card | $0.042 / 1M input tokens — vendor-reported; output free because none is generated |
|---|---|
| Vendor-circulated | ~$0.0004 / decision — vendor-reported round number; ignores how small a real state is |
| Measured Choice | $0.0000144 — measured on the live API: one Choice over 3 options, 342 input tokens |
| Measured 3-in-1 | $0.0000226 — measured: Choice + Score + Noul in one call, 539 tokens |
| Gap | ~20× cheaper than $0.0004 — same rate card; the difference is state size, not a secret discount |
| 1M calls/month | about $14 – $23 — from the two measured calls; no volume discount assumed |
Quick answer · verified 2026-09-19
- Input
- $0.042 per 1M input tokens
- Output
- Free (no output tokens are generated)
- Latency
- 70–500ms end-to-end
- Context
- 64k tokens
- Rate limits
- 100,000 tokens per second and 80 requests per second (TypeSafe says these are adjusting and can change without notice); either one over the line returns 429
- Free tier
- No free-credit or trial program documented at launch
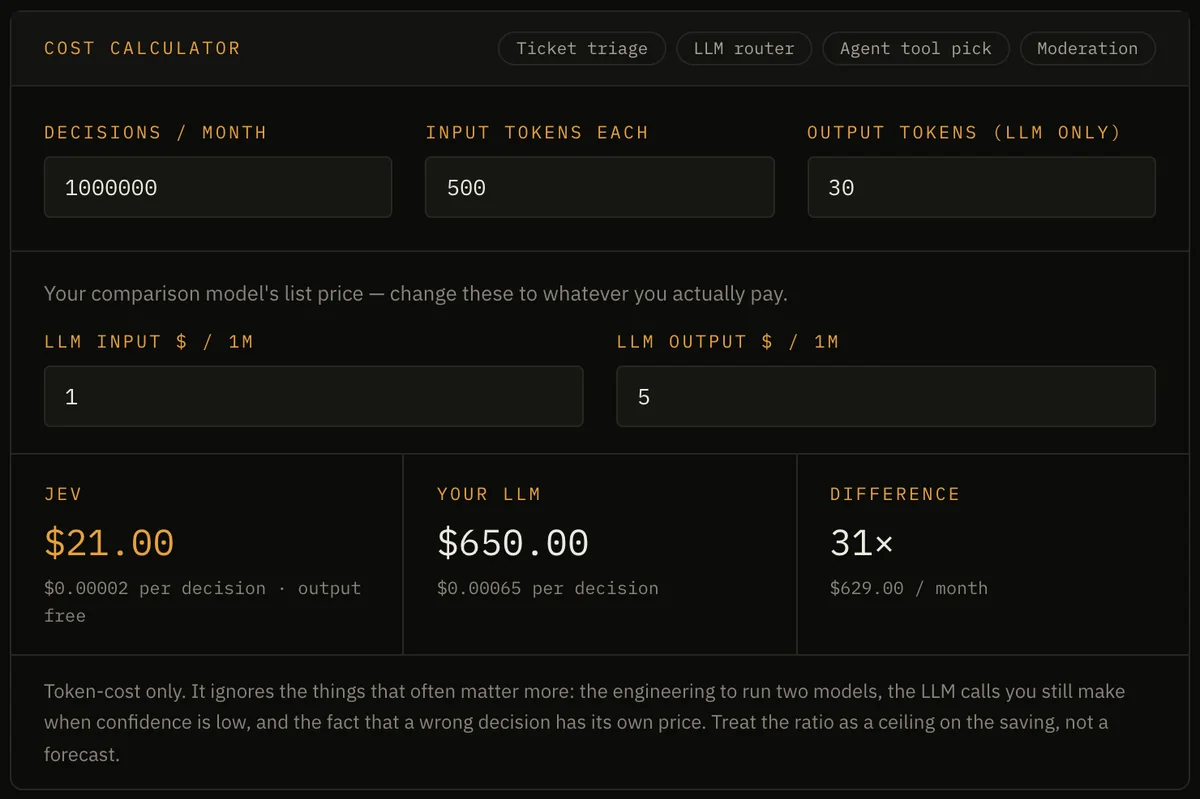
Your comparison model's list price — change these to whatever you actually pay.
Jev
$21.00
$0.00002 per decision · output free
Your LLM
$650.00
$0.00065 per decision
Difference
31×
$629.00 / month
Token-cost only. It ignores the things that often matter more: the engineering to run two models, the LLM calls you still make when confidence is low, and the fact that a wrong decision has its own price. Treat the ratio as a ceiling on the saving, not a forecast.
Measured, not estimated
These are real calls against the live API on 2026-09-18, with the cost as the API itself reported it — not arithmetic from the rate card. One caveat worth stating: that cost field comes from OpenRouter. The first-party API returns input_tokens and output_tokensbut no cost, so going direct means computing spend from tokens yourself:
| Call | Input tokens | Reported cost |
|---|---|---|
| Choice over 3 options | 342 | $0.0000144 |
| Choice + Score + Noul, one call | 539 | $0.0000226 |
| Five Noul signals, one call | 368 | $0.0000155 |
| One Wikirace hop, 48 options | ~1,100 | $0.0000474 |
Why is output free?
Because Jev does not generate any. A chat model bills you per token it writes; Jev returns a decision and a probability distribution from a single forward pass. There is no stream of tokens to meter, so the entire cost sits on the input side.
The most one call can cost
Because Jev pricing is input-only, a single request has a hard ceiling. The context window, 64k tokens, covers the state plus every question, and nothing billable is generated on top of it, so even a request filled to the limit costs under $0.003 at the rate card. Spend grows with volume and with state size, never with a model deciding to say more.
A worked example
Jev pricing is easiest to see on a real workload. Say you are routing support tickets: an average ticket plus your option list is around 500 tokens of state. At $0.042 per 1m input tokens:
500 tokens x 1,000,000 tickets  = 500,000,000 input tokens
500M tokens / 1M x $0.042       = $21.00

One million routing decisions ≈ $21
The same job done by asking a frontier chat model to emit JSON costs orders of magnitude more, runs in seconds rather than milliseconds, and needs parsing plus retry logic you have to maintain. That gap — not the raw number — is the pitch.
Jev pricing on each route
Jev pricing is the same on all three routes: TypeSafe, OpenRouter and the Vercel AI Gateway list $0.042 per million input tokens and nothing for output. What differs between routes is who meters you and whose terms apply.
- TypeSafe AI (first-party) — Official API. Get a key from the console dashboard; check your account for current availability.
- OpenRouter — Live as `typesafe/jev-1.13` at $0.042/M input, $0 output, 32K context, ~99.8% availability. Note it will not show up in OpenRouter's default model list — see the gotcha below.
- Vercel AI Gateway — Also carries it, as model id `typesafe-ai/jev`, at the same $0.042/M input, $0 output.
- Cloudflare AI Gateway — Announced by Cloudflare as live and callable from Workers. Third-party announcement rather than TypeSafe documentation — verify the model id against Cloudflare's own catalogue before you build on it.
Gateway listings matched the first-party rate at our last check, but a gateway can add a margin later, and its limits and terms apply instead of TypeSafe's. Check both before committing production traffic.
No TypeSafe key yet? This site sells prepaid credits for its own endpoint, which forwards to Jev: one credit per started 1,000 input tokens of a request. That is a separate price list from the Jev pricing above, and it is on Plans.
Is self-hosting cheaper?
Rarely, at today's Jev pricing. A 4B open model on your own GPU has a real hourly floor whether or not you are serving traffic, plus the engineering to build and calibrate it. At $21 per million decisions, the hosted API is hard to beat on cost alone — self-hosting makes sense when you need data residency, offline operation or no vendor dependency. See the open-source options if that is you.
For an hourly number to hold against a GPU, TypeSafe gives one for its own Doom bot: about $7 an hour at roughly ten queries a second. That is the vendor's figure, not ours.
Practical questions
What does one Jev decision actually cost?
At the published input rate of $0.042 per million tokens, a 342-token request costs about $0.0000144, excluding any gateway or service markup. A decision has no fixed token count: state length and question definitions change the cost. Jagent uses its own credit pricing, so this upstream calculation is not the price of a Jagent credit.
Method and evidence · Checked 2026-10-04