Measured
Jev Router, measured: which model it picks and what it costs
Jev Router is TypeSafe AI's model router on OpenRouter: one model id that chooses a chat model and a reasoning effort for every request. We sent it 24 requests on 2026-10-02, from a one-word fact to a proof, and recorded every choice it made.
Quick answer · verified 2026-10-02
What does Jev Router do, and what did it cost?
Jev Router uses Jev, TypeSafe's decision model, to read each request and choose which chat model should answer it and how hard that model should think. You send an ordinary chat request to one model id; you get back an ordinary chat answer, from whichever model Jev Router picked.
| Model id | typesafe/jev-router — listed on OpenRouter 2026-09-25 |
|---|---|
| Price | the chosen model's list price — no routing fee in our run |
| Our run | 24 requests, $0.0056 in total |
| Median time | 1.27 s — end to end, including the chosen model |
| Objective answers | 15 of 16 right — the miss was cut off by our token cap |
What Jev Router is
OpenRouter's listing describes Jev Router as picking the best model and reasoning effort for each request, balancing quality, speed and cost, and adapting as a conversation evolves. It runs on Jev, the System One model TypeSafe launched on September 15, 2026. Jev itself never writes text; in Jev Router it makes one decision — which model — and the model it chose writes the reply.
It accepts the usual chat parameters, including tools, structured outputs and a reasoning setting, and OpenRouter lists text, image, file, audio and video as inputs. TypeSafe has not published which models are in its pool or how it scores them, which is why the rest of this page is a measurement rather than a summary.
How to call Jev Router
Jev Router is reached like any OpenRouter model: the OpenAI-compatible endpoint with your OpenRouter key and the model id. Ask for usage to see what each call cost; the response's model field names the model that actually answered.
curl https://openrouter.ai/api/v1/chat/completions \
  -H "Authorization: Bearer $OPENROUTER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "typesafe/jev-router",
    "messages": [{"role": "user", "content": "Prove that the square root of 2 is irrational."}],
    "max_tokens": 2000,
    "usage": {"include": true}
  }'
Leave max_tokens generous. Jev Router can choose a reasoning model, and reasoning tokens count against the same limit — the one miss in our run below is exactly that.
What Jev Router picked, request by request
| Request | Jev Router chose | Time | Billed | Answer |
|---|---|---|---|---|
| Capital of Australia | GPT-6 Luna | 2.3 s | $0.00000 | right |
| Planet closest to the Sun | GPT-6 Luna | 1.0 s | $0.00000 | right |
| Good morning in French | DeepSeek V4.1 Flash | 0.7 s | $0.00007 | right |
| 17 × 23 | GPT-6 Luna | 1.4 s | $0.00001 | right |
| 1234 + 5678 | Gemini 3.8 Flash | 2.7 s | $0.00025 | right |
| Pens at 3 for $2 | GPT-6 Luna | 1.1 s | $0.00002 | right |
| A three-term syllogism | GPT-6 Luna | 1.1 s | $0.00002 | right |
| Review: positive or negative | GPT-6 Luna | 1.3 s | $0.00001 | right |
| Pull an email from a sentence | GPT-6 Luna | 1.4 s | $0.00001 | right |
| English into Japanese | DeepSeek V4.1 Flash | 0.7 s | $0.00019 | open-ended |
| One-sentence summary | GPT-6 Luna | 1.1 s | $0.00002 | open-ended |
| List into a markdown table | DeepSeek V4.1 Flash | 0.8 s | $0.00009 | right |
| Fibonacci in Python | GPT-6 Luna | 4.4 s | $0.00003 | right |
| Fix a one-line bug | GPT-6 Luna | 1.4 s | $0.00002 | right |
| Top five customers in SQL | DeepSeek V4.1 Flash | 1.0 s | $0.00030 | right |
| Haiku about rain | GPT-6 Luna | 1.3 s | $0.00001 | open-ended |
| Names for a coffee shop | GPT-6 Luna | 1.0 s | $0.00002 | open-ended |
| Questions about a job offer | GPT-6 Luna | 1.1 s | $0.00006 | open-ended |
| Inflation, asked in Chinese | GPT-6 Luna | 1.0 s | $0.00002 | open-ended |
| Proof that √2 is irrational | Claude Sonnet 5.5 | 1.9 s | $0.00239 | right |
| Divisors of 360 | GPT-6 Luna | 1.3 s | $0.00002 | right |
| Sum of multiples of 3 or 5 | Gemini 3.8 Flash | 2.9 s | $0.00151 | cut off at our cap |
| Postgres migration plan | DeepSeek V4.1 Flash | 0.8 s | $0.00050 | cut off at our cap |
| Kyoto trip, third turn | GPT-6 Luna | 1.3 s | $0.00007 | open-ended |
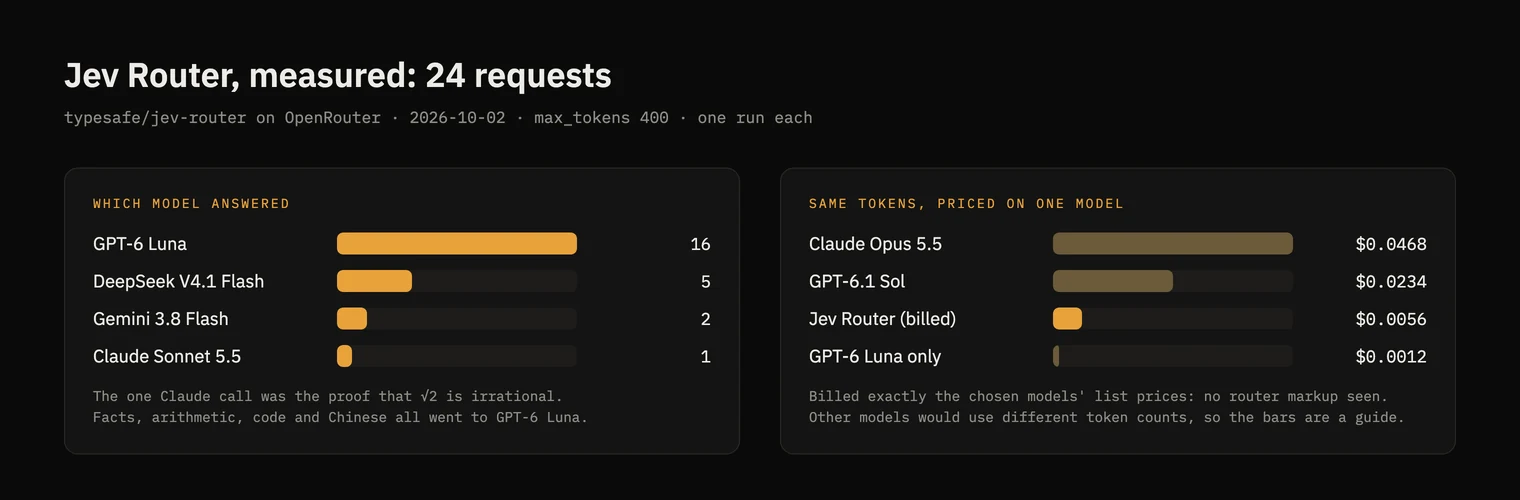
The pattern in what Jev Router picked is plain. For short facts, arithmetic, classification, code and even the question in Chinese, Jev Router picked GPT-6 Luna, the cheapest model it used. The French greeting, the translation, the SQL, the table and the migration plan went to DeepSeek V4.1 Flash. Jev Router picked Gemini 3.8 Flash twice, on arithmetic and counting, and once, for the proof, Claude Sonnet 5.5 — the most expensive call in the run, at about a quarter of a cent.
What Jev Router cost
For all 24 requests together Jev Router billed $0.0056, and every call matched the list price of the model that answered it to the last digit, so the router added no fee of its own. Priced on a single model, the same token counts would have cost $0.0468 on Claude Opus 5.5 and $0.0234 on GPT-6.1 Sol — 8.3 and 4.1 times as much. On GPT-6 Luna alone they would have cost $0.0012, a fifth of what Jev Router billed.
That last comparison is the honest one. Jev Router saves money against sending everything to a flagship, not against sending everything to the cheapest model; what it buys you is the escalation — the proof went to a stronger model without anyone writing a rule for it. A different model would also have used a different number of tokens, so read the single-model figures as a guide. To price your own traffic on any model, use the LLM cost calculator.
Where Jev Router went wrong
Once. For "Find the sum of all integers n with 1 ≤ n ≤ 100 that are divisible by 3 or 5. Give the number." Jev Router picked Gemini 3.8 Flash, which spent 385 of its 396 output tokens reasoning and reached our 400-token cap before writing the answer. That is our limit, not a wrong answer — but it is the failure you will see in production if you cap replies tightly, because you do not choose the model and some of the models Jev Router picks think before they answer. Every other request with a checkable answer came back right: 15 of 16.
Jev Router or Jev itself?
Use Jev Router when you want an answer and would rather not maintain routing rules. Call Jev directly when you want the decision: your own list of models or tools as options, your own confidence threshold, and the choice logged in your code, at $0.042 per million input tokens for the decision alone. The model routing use case shows that pattern with measured output, and Jev in an agent applies it to tool calls.
Skip both when every request needs the same model for consistency or compliance, or when your traffic is all easy — in our run, one cheap model would have been cheaper still.
Jev Router questions
What is Jev Router?
A model router TypeSafe AI runs on OpenRouter as typesafe/jev-router. It uses Jev, TypeSafe's decision model, to choose which chat model and how much reasoning effort to use for each request, then returns that model's answer.
Does Jev Router cost extra?
Not in our run: across 24 requests it billed exactly the list price of the models it chose, $0.0056 in total, with no routing fee on top.
Which models does Jev Router use?
TypeSafe has not published a list. In our 24 requests it picked GPT-6 Luna (16), DeepSeek V4.1 Flash (5), Gemini 3.8 Flash (2), Claude Sonnet 5.5 (1).
Can Jev Router read images?
OpenRouter lists text, image, file, audio and video input for it. Our test sent text only, so we have not checked how it routes the other kinds.
Method: 24 prompts, one run each, through OpenRouter on 2026-10-02, with max_tokens at 400. Answers with a fixed result were checked by string match; open-ended ones were not scored, so what Jev Router picked for them is recorded but not graded.