Checked 2026-10-08
Decision models: all thirteen on the Decisions API, one by one
Decision models read an input and answer typed questions — pick one option, place it on a rubric, or say how likely a statement is — with probabilities instead of written text. Jev was the first. These are all the decision models you can call today, what each one is, and what it did on the same test.
Quick answer · verified 2026-10-08
Which decision models are there?
TypeSafe Jev 1.13, OpenAI GPT-6 Luna Decisions, Cloudflare Clef, Cloudflare Clef Flash, Perplexity Decider V1.1 27B, Upstage Solar Decide, Upstage Solar Decide Flash, Liquid AI d1, Inception Mercury Decide (free), Together AI Tev1 4B Experimental, Jared Palmer Kev 4B, Respan Span-01 and Respan Span-01 Lite (free). All of them answer through the same Decisions API on OpenRouter, and GPT-6 Luna also through OpenAI's own /v1/decisions; one Jagent key calls any decision model on the list.
| Models | 13 — from 10 makers |
|---|---|
| Open weights | Clef, Clef Flash, Tev1 4B Experimental and Kev 4B |
| Read images | GPT-6 Luna Decisions, Clef, Clef Flash and Decider V1.1 27B |
| Free tier | Mercury Decide (free) and Span-01 Lite (free) — rate-limited |
Under each decision model: its id and facts, then our measured line — simple choices / 59 to 77 options / predicates / share of 90%-sure answers that were wrong / median latency from US East.
What is Jev 1.13?
The first System One model: a typed choice, score or yes/no with calibrated probabilities instead of text. Served on OpenRouter by TypeSafe alone, and on TypeSafe's own API at api.typesafe.ai/v1/systemone.
jev-latest · TypeSafe · 2026-09-18 · $0.042/M · text-only · 32K context
94% / 79% / 95% / 11.5% / 184 ms
What is GPT-6 Luna Decisions?
GPT-6 Luna served through OpenAI's Decisions API (POST /v1/decisions, public beta since 2026-10-06). Up to 200 questions about the same input in one request. Reads text, JSON or images.
gpt-6-luna · OpenAI · 2026-10-06 · $0.1/M · reads images · 1050K context
94.1% / 79.8% / 93.5% / 9.2% / 138 ms
What is Clef?
Cloudflare's open-source 27B multimodal decision model, a fine-tune of Qwen3.8-27B on Workers AI. Two hosts on OpenRouter: Cloudflare at $0.24 per million input tokens and Prime Intellect at $0.042, slower. Workers AI reads roughly the first 2K tokens of a long text state; the rest is not seen.
cloudflare/clef · Cloudflare · 2026-10-01 · $0.042–0.24/M · reads images · 66K context · open weights
95% / 89% / 97% / 2.3% / 313 ms
What is Clef Flash?
The fast 9B member of the Clef family, a fine-tune of Qwen3.5-9B on Workers AI. Several hosts on OpenRouter, from $0.021 per million input tokens. Same 2K-token reading limit on long text as Clef.
cloudflare/clef-flash · Cloudflare · 2026-10-01 · $0.021–0.09/M · reads images · 66K context · open weights
92.6% / 92% / 97% / 4.2% / 369 ms
What is Decider V1.1 27B?
A new checkpoint of Perplexity's decision model, same contract as Decider V1 27B. Up to 128 questions about the same content in one request. Reads text, JSON or images.
perplexity/pplx-decider-v1.1-27b · Perplexity · 2026-10-07 · $0.02/M · reads images · 262K context
96% / 85% / 95.5% / 4.6% / 269 ms
What is Solar Decide?
Upstage's structured decision model on Solar Mini 4, served as a System One endpoint. A 512K context window, so a whole document can be the state. Built on Solar Mini 4, noted for its Korean. Listed at 50% off on 2026-10-08.
upstage/solar-decide · Upstage · 2026-09-28 · $0.05/M · text-only · 524K context · at most 26 options
94.6% / refused / 93% / 13.7% / 559 ms
What is Solar Decide Flash?
The low-latency variant of Solar Decide, built on Solar Mini 4. Tuned for consistent response times; keeps the 512K context.
upstage/solar-decide-flash · Upstage · 2026-10-08 · $0.05/M · text-only · 524K context · at most 26 options
94.1% / refused / 91.5% / 9.5% / 597 ms
What is d1?
Liquid AI's structured decision model, served as a System One endpoint. Hosted by Liquid alone on OpenRouter.
liquid/d1 · Liquid AI · 2026-10-01 · $0.04/M · text-only · 66K context
96.5% / 86% / 96.5% / 3.2% / 322 ms
What is Mercury Decide (free)?
Inception's structured decision model, served as a System One endpoint. Inception states up to 14 decisions per second. Free on OpenRouter, so rate-limited upstream.
inception/mercury-decide:free · Inception · 2026-09-30 · free · text-only · 33K context
95.6% / 85% / 94% / 5.4% / untimed
What is Tev1 4B Experimental?
An experimental supervised fine-tune of Qwen3.5-4B, described for choosing among 2-24 options. Together publishes the data recipe and training code. Natively returns one option letter from a chat endpoint; the Decisions API wraps it.
togethercomputer/tev1-4b-experimental · Together AI · 2026-09-30 · $0.042/M · text-only · 33K context · at most 20 options · open weights
90.4% / refused / 93.5% / 5.1% / 136 ms
What is Kev 4B?
A small open-weight decision model: a LoRA adapter and pointer head on Qwen3.5-4B-Base, on the same contract as Jev. Apache-2.0; the family also has 0.8B and 9B checkpoints (github.com/jaredpalmer/kev). An 8K context, the smallest here.
jaredpalmer/kev-4b · Jared Palmer · 2026-09-25 · $0.042/M · text-only · 8K context · open weights
95% / 78.5% / 91% / 2.6% / 359 ms
What is Span-01?
A behaviour scoring model: the probability that each behaviour you describe is present in a conversation. Meant for evaluating, guarding and monitoring LLM and agent output.
respan/span-01 · Respan · 2026-09-26 · $0.02/M · text-only · predicate questions only
— / — / 93.5% / — / 128 ms
What is Span-01 Lite (free)?
The lighter tier of Span-01: yes/no behaviour probabilities over a conversation.
respan/span-01-lite:free · Respan · 2026-09-26 · free · text-only · predicate questions only
— / — / 93.5% / — / untimed
How to choose between decision models
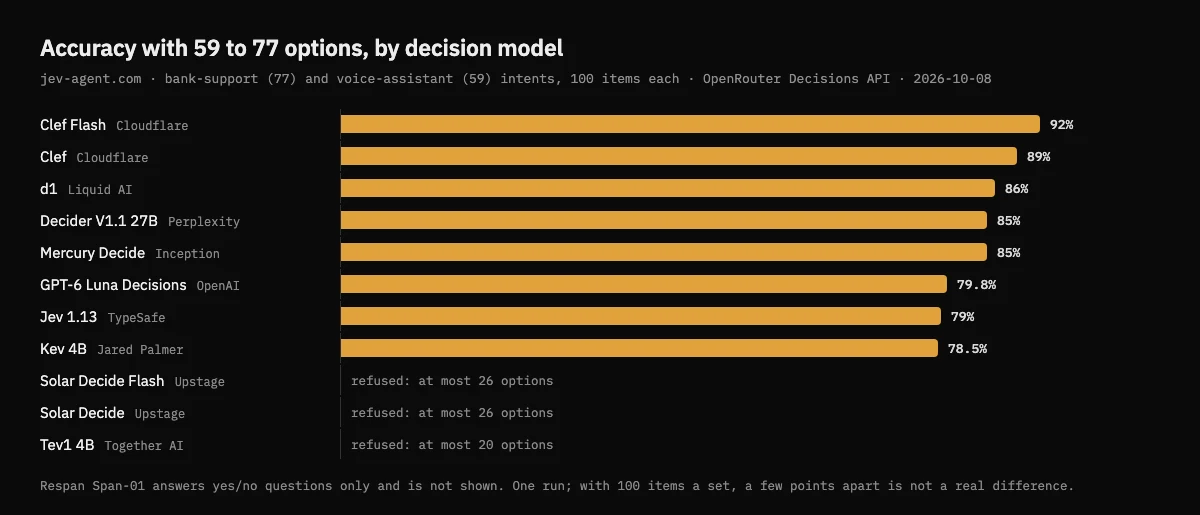
Start from what the decision needs. The decision models barely differ on a simple two-way gate, so pick on speed and price there. Dozens of intents rule out Solar Decide and Tev1 and favour the models that held up at 77 options. A threshold that triggers an action needs confidence you can trust, so read the confident-and-wrong rate before the accuracy. Images narrow it to GPT-6 Luna Decisions, Clef, Clef Flash and Decider V1.1 27B; a long document points to the Solar models, and away from Clef's 2K-token reading limit.
Then test the decision models on your own items: the playground has a model picker, and POST https://jev-agent.com/api/v1/decisions takes OpenAI's Decisions API request with any model id above. The full accuracy, calibration and latency tables are on Decisions API vs Jev, and what a System One model is in the first place is on System One explained.