Jev vs LLM: which one should make the decision?
The comparison people reach for first, and the one that misleads fastest. One model produces text and the other produces a decision, so the useful Jev vs LLM question is which parts of your pipeline are which.
Jev vs LLM: which one should you use?
Use an LLM if the step ends in a sentence; use Jev if it ends in a branch. An LLM is better at almost everything, including accuracy. Jev is roughly 75x cheaper and 25x faster at the one narrow thing it does: picking from a set you already know.
It makes a decision cheap enough to make many of them — gate every tool call, score every retrieved passage. Most real systems run both: Jev picks, the LLM writes.
| Accuracy | the LLM wins — vendor's own table: Jev 67.8%, GPT-5.6 Sol 74.1%, Opus 5 73.1% |
|---|---|
| Latency | 0.4s vs 10–38s — vendor-reported, per decision |
| Cost per decision | $0.0004 vs $0.03–$0.18 — vendor-reported |
| Can it write? | no — Jev generates no text at all — not a summary, not a word |
Quick answer · verified 2026-09-19
Side by side
| Axis | Jev | A frontier LLM |
|---|---|---|
| Output | A typed decision — option, probabilities, confidence | Tokens. Anything you can describe in words |
| Context | 64k per request, 32k state + longest question | 200k – 1M+ depending on model |
| Answer space | Fixed at request time, up to 255 options | Open — it can invent an option you did not list |
| Calibration | A probability per option, trained for it | Logprobs at best; verbalised confidence is not calibrated |
| Streaming | Nothing to stream — one structured answer | Token by token |
| Self-hosting | None. Closed weights, hosted API only | Open-weight families are self-hostable |
Accuracy: the vendor does not claim the win
The marketing headline — 193.6x faster and 444.6x cheaper than frontier llms in peak in-house testing. — is about speed and cost, and people hear it as being about quality. TypeSafe's own table:
| Model | Accuracy | Cost | Latency |
|---|---|---|---|
| Jev | 67.8% | $0.0004 | 0.4s |
| GPT-5.6 Terra | 67.9% | $0.0304–$0.1761 | 10–38s |
| Opus 5 | 73.1% | $0.0304–$0.1761 | 10–38s |
| GPT-5.6 Sol | 74.1% | $0.0304–$0.1761 | 10–38s |
Our own ground truth agrees. On 27 labelled tickets run 3 times each, Jev and Mistral Small scored 27/27 on every pass; Gemini 2.5 Flash Lite and GPT-5 nano each missed the same ticket. Only Jev adds a confidence that moves when the question gets harder — 0.979 on clear tickets, 0.841 on ambiguous ones. Full table on the benchmarks page.
We ran it ourselves
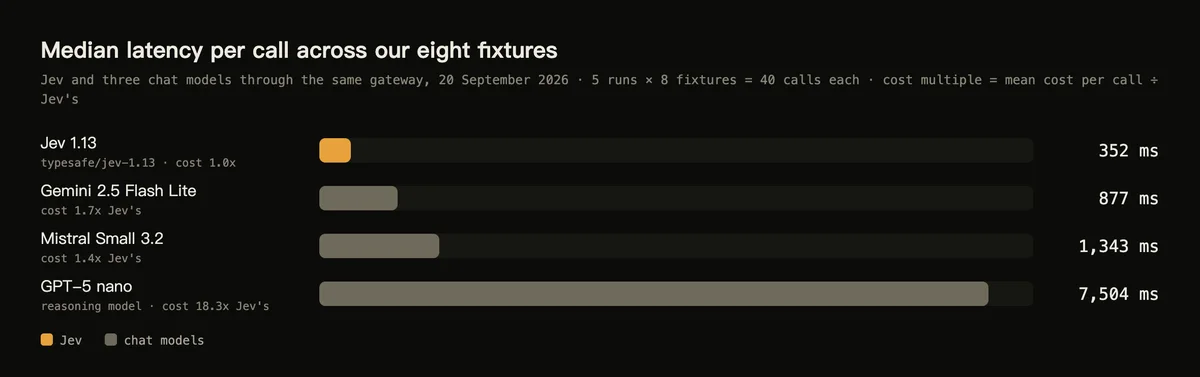
Our own Jev vs LLM test: a Choice, a Score and a Noul about one support ticket, put to Jev and three chat models through the same gateway, five runs each, on 2026-09-20, with the shape spelled out to the chat models.
| Model | Median | Out tok | Cost | Valid JSON | Right type |
|---|---|---|---|---|---|
| typesafe/jev-1.13 | 430ms | 85 | $0.0000226 | 5/5 | 5/5 |
| openai/gpt-5-nano | 8,332ms | 864 | $0.0003154 | 5/5 | 4/5 |
| google/gemini-2.5-flash-lite | 911ms | 35 | $0.0000402 | 5/5 | 2/5 |
| mistralai/mistral-small-3.2-24b | 1,890ms | 35 | $0.0000348 | 5/5 | 5/5 |
So the typing is ergonomics, not reliability: with Jev it is the contract, with a chat model a flag to keep set. What survives the correction is latency and cost, and those gaps do not depend on how the prompt was written.
Values drift too. On urgency, mistral-small said 2 four times and 3 once, Gemini said 2, GPT-5-nano 3. Jev said 2.64 — High, leaning Urgent — within 2.63–2.68 every run, and churn risk 0.99 five times where Mistral wandered from 0.8 to 1.0. A model forced to round cannot tell you it was close.
Against a cheap non-reasoning model Jev is about 2x faster and 1.8x cheaper — nothing like the vendor multiples. The large gaps appear against gpt-5-nano, which spent 864 output tokens thinking. Most of Jev's cost advantage is that there is no output to bill.
The arithmetic that usually decides it
A million decisions a month — a mid-sized support queue or moderation pipeline — at the vendor's own per-decision figures:
Jev
$400
1,000,000 × $0.0004, with no output tokens to pay for.
Frontier LLM
$30,400 – $176,100
1,000,000 × $0.0304–$0.1761, before retries and discarded reasoning tokens.
Where the LLM wins outright
Not a matter of taste — TypeSafe documents most of these itself as jagged edges in jev-1.13.
- Anything that ends in words. Summaries, replies, code. Jev is not trained to generate text.
- Open-ended answer spaces. If you cannot enumerate the options, there is no encoding of the question.
- Arithmetic, counting and dates. Jev reads dates as text, and counts by recognising the shape of an answer rather than tallying.
- Multi-hop reasoning. A question about a property of a property costs accuracy: System One means fast judgement, not deliberation.
- Agentic loops. Jev can pick the tool; it cannot write the arguments or read the result back into prose.
Where Jev wins outright
- Decisions per dollar. Two orders of magnitude is a different design space: questions that were never worth three cents to an LLM become worth asking.
- A probability you can branch on. A distribution and a confidence, so code can route, defer or escalate — and similar inputs get similar numbers, so a threshold holds over time. An LLM's stated confidence is not calibrated.
- Latency inside a request. Sub-second decisions can sit in a synchronous path; a 20-second reasoning call cannot.
The configuration that beats either one alone
The strongest published result on Jev is Jev as a signal generator: in a 2,000-email phishing study its single verdict lost clearly to Claude Haiku 4.5, but a plain logistic regression over five cheap signal questions in the same call reached 95.1% accuracy with AUROC 0.988. So do not port one big LLM prompt into one big Jev question. Day to day, Jev routes, the LLM takes the cases Jev is unsure about and writes what the user reads, and a fallback you actually exercise means you are not betting the product on a 67.8%.
Jev vs LLM, in one pass
Reach for Jev when
The options are known, the volume is high, the answer feeds an if, and you want a probability rather than a verdict.
Reach for the LLM when
A human reads the output, the answer space is open, the task needs several steps of reasoning, or the volume is low enough that the cost difference is noise.
At low volume it does not matter: ten thousand decisions a month is $4 against $304, not a reason to add a second vendor and a second SDK. The case for Jev gets strong when decisions are many, repetitive, and in the way.
Common questions
When should I use an LLM instead of Jev for routing?
Use an LLM when the next step needs an open-ended plan, newly invented options, generated arguments or an explanation. Jev fits a choice among handlers or models you can name before the call. In a hybrid, code asks Jev for the bounded choice and hands uncertain or complex cases to an LLM or a person.
Source · Checked 2026-10-04
Is Jev better than GPT or Claude?
Not at accuracy. TypeSafe's own evaluation puts Jev at 67.8%, below GPT-5.6 Sol at 74.1% and Opus 5 at 73.1%. The claim is comparable accuracy at roughly 1/100th the cost and 1/50th the latency.
Can Jev replace my LLM?
Only the decision steps. Jev emits no text at all, so anything that ends in a sentence still needs an LLM.
Is Jev cheaper than an LLM?
For decisions, by two orders of magnitude: $0.042 per million input tokens with no output tokens, and $0.0004 a decision in TypeSafe's own table against $0.0304–$0.1761 for frontier models.
When should I not use Jev instead of an LLM?
When the answer is text, the options cannot be enumerated, or the task needs arithmetic, dates or several hops of reasoning — failure modes TypeSafe documents for jev-1.13.