Developers · Tools API
Essay grading API, MCP server and Claude skill
Everything the graders on this site do — essays against built-in or custom rubrics, resumes against job postings — as a REST API, as a remote MCP server for Claude, Cursor and other agents, and as a Claude skill. One API key, one balance, and the same results the pages show.
Three ways in
| Surface | Best for | Address |
|---|---|---|
| REST API | Your backend, a grading queue, a batch job | /api/v1/tools/grade, /api/v1/tools/resume-check |
| MCP server | Agents in Claude Code, Claude Desktop, Cursor, VS Code | https://jev-agent.com/api/mcp |
| Claude skill | Claude calling the API itself, no server config | /skills/jagent-graders.zip |
All three use the same jv_live_ key for the essay grading API, issued after a Google sign-in at API access, and spend the same balance. The grading underneath is Jev, TypeSafe AI's judgment model: it answers typed questions with a probability for every possible answer and writes no text, so every score comes with the distribution behind it.
The essay grading API
The essay grading API is one endpoint: POST /api/v1/tools/grade grades one essay, or a batch, against a rubric. Choose essay for class essays (six criteria and a letter grade), common-app for personal statements, sat for the SAT School Day essay, or custom for your own rubric.
curl https://jev-agent.com/api/v1/tools/grade \
  -H "Authorization: Bearer $JAGENT_API_KEY" \
  -H "content-type: application/json" \
  -d '{"rubric": "essay", "level": "high school",
       "assignment": "Should high schools start later?",
"essay": "…"}'Runs on the page's allowance for visitors without an account; with a key, the same body goes to /api/v1/tools/grade and adds a usage block.
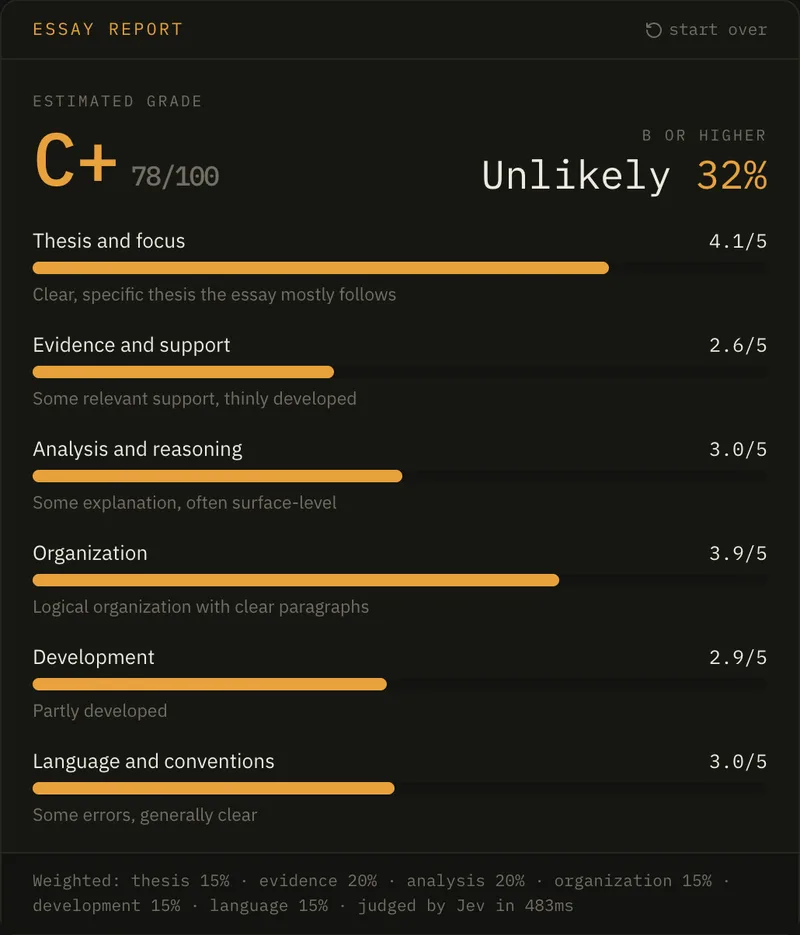
The response for our calibration essay of middling quality, trimmed:
{
  "result": {
    "percent": 78, "letter": "C+",
    "verdict": { "label": "B or higher", "yes": 0.31 },
    "criteria": [
      { "name": "Thesis and focus", "level": "Clear, specific thesis the essay mostly follows", "index": 3.1, "levels": 5 },
      { "name": "Evidence and support", "level": "Some relevant support, thinly developed", "index": 1.58, "levels": 5 }
    ],
    "checks": [{ "label": "Length", "status": "warn", "detail": "209 words — short for most essay assignments…" }],
    "stats": { "words": 209, "paragraphs": 5, "readingGrade": 4.5 }
  },
  "usage": { "credits_charged": 2, "credits_remaining": … }
}
index is the essay's exact position on the criterion's ladder, 0 at the bottom; the fraction says which way it leans. verdict.yes is a probability, and checks are counted facts that never feed the grade. Limits: 100 to 20,000 characters per essay, and for batches up to 30 submissions, eight criteria and a 3- to 6-point scale.
Batch grading on your own rubric
{
  "rubric": "custom",
  "custom": { "points": 4, "criteria": [
    { "name": "Claim", "description": "States a clear, arguable claim" },
    { "name": "Evidence", "description": "Supports the claim with specific evidence" }
  ]},
  "submissions": [{ "name": "A", "text": "…" }, { "name": "B", "text": "…" }]
}
Each submission is graded in its own call, five at a time, so a paper's score depends only on the paper and the rubric. Three essays came back together in 0.54 seconds in our test.
The resume check API
POST /api/v1/tools/resume-check takes resume and an optional job_description, and returns a 0–100 match score, the posting's keywords found and missing, ATS format checks, the level fit and the probability a recruiter would move the resume to interview — the same report as the AI resume checker page. A resume plus a posting is about 1,100 input tokens, or 2 credits.
The MCP server
The server speaks Streamable HTTP at https://jev-agent.com/api/mcp. Listing its tools needs no key, so a client can see what is offered before anyone signs up; calling a tool needs the key in an Authorization header. In Claude Code:
claude mcp add --transport http jagent https://jev-agent.com/api/mcp \
  --header "Authorization: Bearer $JAGENT_API_KEY"
In Cursor's mcp.json (VS Code's file is the same idea under a servers key, with "type": "http"):
{ "mcpServers": { "jagent": {
    "url": "https://jev-agent.com/api/mcp",
    "headers": { "Authorization": "Bearer jv_live_…" } } } }
Clients that only run local servers can reach it through the mcp-remote bridge, passing the same header. The seven tools:
| check_resume | Match a resume to a posting: score, missing keywords, format checks, interview probability. |
| grade_essay | One essay against the essay, Common App or SAT rubric. |
| grade_with_rubric | Up to 30 submissions against a rubric the agent supplies. |
| judge_yes_no | Probability that the answer to a yes/no question about a text is yes. |
| judge_choice | The best of several options, with a probability for each. |
| judge_score | A position on an ordered scale the agent defines. |
| compare_versions | Which of two versions is stronger, asked in both orders. |
Every tool returns a one-line summary for the model to read, followed by the full result as JSON with the credits charged. compare_versions asks its question twice with the order swapped, because on close calls the model favors whichever option it read second — 0.90 in one order and 0.53 the other way round for the same pair, in our tests.
The Claude skill
The jagent-graders skill is a single SKILL.md: when to reach for the graders, the two REST calls, how to read a level and an index, and what not to ask for. In Claude Code, unzip it into ~/.claude/skills/ and set JAGENT_API_KEY in the environment; in the Claude apps, upload the zip where skills are managed. Claude then calls the API with curl whenever a conversation turns to grading an essay or checking a resume, and does the rewriting itself.
Billing and errors
The essay grading API bills like the rest of the site: one credit buys 1,000 input tokens, rounded up with a minimum of one per call, charged after the call succeeds. A 400-word essay graded on the six-criterion rubric is about 1,300 tokens — 2 credits; each extra submission in a batch adds its own tokens. There is no output-token charge, because the model produces none.
What it does not do
It does not rewrite, summarize or generate feedback prose; it grades, and your code or your agent writes. It does not detect plagiarism or AI-written text, and its grades are estimates from written rubrics, not official scores. It keeps nothing: request bodies are scored and discarded, and the call log records the endpoint and the credits, never the text.
Questions
Does the essay grading API work in other languages?
Yes, for the essay itself. We graded a strong and a weak essay in Chinese, Spanish, German and Japanese with the same English rubric: the strong ones scored 3.95 to 3.99 of 4 on thesis and the weak ones 2.36 to 2.65, much like the English pair. Field names and error messages are in English.
Is there a sandbox or test mode?
No separate sandbox. A new key comes with a small monthly allowance of credits, enough to grade a couple of essays and see the real response, and a failed request is never charged.
Can an agent use it without the MCP server?
Yes. The Claude skill teaches Claude to call the REST endpoints with curl, and any agent that can make an HTTP request can do the same with the examples above.