Jev vs BERT: a decision model or a fine-tuned classifier
The comparison that is actually close. An LLM and a decision model do different jobs; a decision model and a fine-tuned BERT do the same job, and which one wins turns almost entirely on whether you already have labels.
Jev vs BERT, line by line
| Axis | Jev | Fine-tuned BERT |
|---|---|---|
| Labelled data needed | None. You write option descriptions instead | Hundreds to tens of thousands of examples per class |
| Time to first result | Minutes | Days to weeks, most of it labelling |
| Cost per 1M calls | $21 at a 500-token state; more as the state grows | Near zero at inference — the cost is labels, training and upkeep |
| Changing the taxonomy | Edit a string, ship | Relabel, retrain, revalidate, redeploy |
| Ceiling on one fixed task | General model, general ceiling | Higher, given enough clean labels |
| Calibration | Trained for it; a probability per option | Yours to earn — usually needs Platt scaling or isotonic regression |
| Data residency | Hosted API only; the text leaves your network | Runs wherever you run it |
Jev vs BERT on cost: what a classification costs
The two sides are usually quoted in different units. Jev charges $0.042 per million input tokens and nothing for output. So a classification whose state is a 500-token support ticket costs:
500 tokens / 1,000,000 × $0.042 = $0.000021 per call
                              × 1,000,000 calls = $21
TypeSafe's own evaluation quotes $0.0004 per decision, which implies a state around twenty times larger — a realistic reminder that your cost is set by how much context you send, not by the number of questions you ask. Asking five questions about one state costs the same as asking one, because the state is ingested once.
Where a fine-tuned BERT wins
- One task, lots of labels, stable taxonomy. This is what fine-tuning is for. A small model trained on your own distribution beats a general one on your own distribution.
- Data that cannot leave. Jev is a hosted API with closed weights. There is no VPC option and no air gap, so a residency rule ends the discussion.
- Numeric and structural judgements. TypeSafe documents that jev-1.13 does not count reliably, cannot compare dates as ordered quantities, and is weak on numeric representations such as hex colours. A classifier over engineered features has no such problem.
- Very high volume with a large state. Cost scales with tokens sent. At tens of millions of long documents, self-hosted inference wins on pure economics.
- Latency floors. A local encoder answers in single-digit milliseconds. Jev quotes 70–500ms end to end, and from a machine far from the host the network alone can eat 200ms before the model starts.
Where Jev wins over BERT
- You have no labelled data. This is the big one. The cold start that costs a classifier project its first month costs Jev an afternoon of writing option descriptions.
- The taxonomy is still moving. Adding a class is an edit to a string, not a relabelling exercise. Products in their first year change categories constantly.
- You need many judgements, not one. A classifier answers the question it was trained on. One Jev call can carry a dozen unrelated questions about the same state for the price of sending the state once.
- The long tail. Classes with forty examples are where fine-tuning struggles most and where a written description works fine.
- Calibration out of the box. You get a probability per option from a model trained to be calibrated, rather than a softmax you have to post-hoc calibrate yourself.
And where embeddings fit
An embedding model turns text into a vector for measuring similarity; it does not answer a question. Embeddings plus a nearest-neighbour lookup is a cheap classifier, but it still needs labelled neighbours. Use embeddings for retrieval and Jev for the judgement about what came back — see reranking retrieved passages.
Can you fine-tune Jev like BERT?
No. Trained with RLCD for calibrated decisions. No per-account fine-tuning or LoRA — the same weights serve every account. What you tune instead is the wording: the option descriptions are the entire prompt surface, and jev-align tunes them against your own labels with GEPA, showing each proposed wording change with its score before you accept it. That is the closest thing to fine-tuning Jev.
Two other routes use your labels. Fit a small model on Jev's probabilities, below. Or, if you need weights you can train, start from an open decision model such as Plumb-4B or decider, both Apache-2.0 fine-tunes of Qwen3.5 — see Jev open source models.
The hybrid: five signal questions and a regression
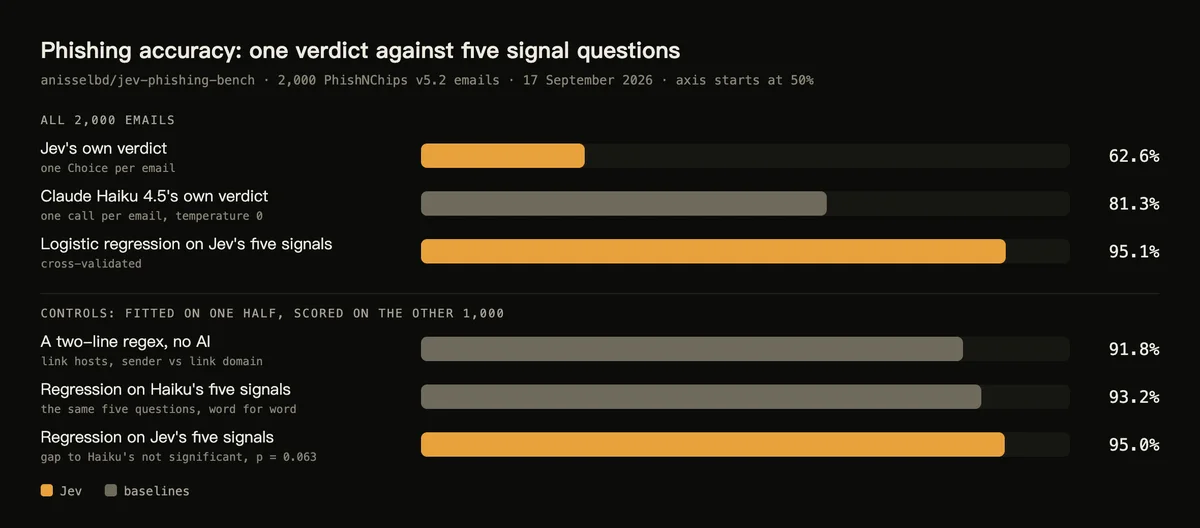
The most interesting published result on Jev is not Jev winning anything. In an independent study of 2,000 phishing emails, Jev's raw verdict was statistically worse than Claude Haiku 4.5 (McNemar p < 0.0001). Then the author asked five cheap signal questions in the same call and fitted a plain logistic regression over the resulting probabilities:
95.1%
accuracy, cross-validated
0.988
AUROC
0.027
expected calibration error
That is Jev used as a feature extractor feeding a classical model. You still need labels to fit the regression, but far fewer than to fine-tune an encoder.
Then the author added controls, and they shrink the claim. On the held-out half, a two-line regex over link hosts scored 91.8%, because this dataset largely separates by construction. Claude Haiku 4.5, asked the same five questions, reached 93.2% against 95.0% for Jev's signals, a gap that is not significant. Splitting the question does the work; Jev's edge is price, about 27 times cheaper than Haiku for signals of similar quality.
# Five cheap signals in one call, then a model you own.
answers = client.system_one(
    model="jev-latest",
    state=email_text,
    questions={
        "sender_mismatch": Noul(instructions="Does the display name disagree with the sending domain?"),
        "urgency":         Noul(instructions="Does the message pressure the reader to act immediately?"),
        "credential_ask":  Noul(instructions="Does it ask for a password, code or payment detail?"),
        "link_mismatch":   Noul(instructions="Does any link text disagree with its destination?"),
        "brand_spoof":     Noul(instructions="Does it impersonate a known brand?"),
    },
).answers

features = [answers[k].noul for k in FEATURE_ORDER]
label = logistic_regression.predict_proba([features])[0][1]Jev vs BERT: how to choose, honestly
Start with Jev when
You are at zero labels, you need to ship this quarter, the categories are still being argued about, or you want to find out whether the task is even learnable before funding a data effort.
Fine-tune BERT when
The task is fixed and valuable, the labels exist or are cheap to get, the volume is enormous, or the data cannot leave your network.
There is also a sequence, which is usually the right answer for a new product: run Jev in production, log every state alongside the decision and whatever ground truth arrives later, and you have built a labelled dataset as a side effect. Train the classifier when the volume justifies it, using the data your Jev deployment generated.
Common questions
Should I use Jev or BERT for intent classification?
Start with a trained classifier when your labels are stable and you have representative labeled examples and a deployment path. Jev is a candidate when you need to define or change the options in each request without training your own model. Compare both on the same held-out inputs; this page's decision guide is not evidence that Jev beats a fine-tuned BERT model.
Method and evidence · Checked 2026-10-04
Is Jev more accurate than a fine-tuned BERT classifier?
Not on a single fixed task where you have plenty of clean labels — a small trained model will usually beat a general decision model on both accuracy and inference cost. Jev wins when the labels do not exist yet, when the taxonomy moves, or when you need many different judgements rather than one.
Can Jev be used as a classifier?
Yes, as a zero-shot one. Jev's Choice question is a classifier you write rather than train: name the classes, describe each in a sentence, and every call returns the winning class with a probability for each. That makes a Jev classifier the fast start this page describes, and the fine-tuned BERT classifier the one you graduate to once labels pile up.
Can Jev replace my existing classifier?
It can replace the ones you have not built yet. Replacing a classifier that already works and is already calibrated on your data is usually a downgrade in accuracy and an upgrade in flexibility — worth it only if the taxonomy is churning or the classifier is expensive to maintain.
Is Jev the same as an embedding model?
No. Embeddings give you a vector so you can measure similarity; Jev gives you a decision over options you named, with a probability for each. Embeddings plus kNN is a real alternative for classification, but it needs labelled neighbours and it cannot answer a question the vectors were not built for.
What is the best of both?
Asking Jev several cheap signal questions in one call and training a small classical model on those probabilities. An independent phishing study reached 95.1% accuracy that way, well above Jev's own single verdict, and TypeSafe documents the same pattern in its AutoResearch cookbook.