Jev agents: using Jev inside an AI agent
Agents spend most of their tokens deciding, not doing. Jev agents hand those decisions — which tool runs next, where a request goes, whether a draft is fit to send, whether the job is done — to a System One model that answers in one typed call, and keep an LLM for the writing.
What are Jev agents?
Jev agents are agent loops in which every branch point is a typed question to Jev rather than a prompt to an LLM. The next tool is a Choice over the tools available this turn; escalation is a threshold on that answer's confidence; “is this safe to send” and “are we done” are Noul questions asked together in one call.
Jev never writes. Tool arguments, replies and anything a person reads still come from an LLM, so each design below is a pairing: Jev picks, the LLM writes.
| One decision | 70–500ms end-to-end — TypeSafe's figure for a whole request |
|---|---|
| Tools per Choice | up to 255 — past that, a two-stage funnel |
| Context | 64k tokens — 32k of it for the state plus the longest question |
| Billing | $0.042 per 1M input tokens — nothing is generated, so no output tokens |
Quick answer · verified 2026-09-19
Pattern 1: tool selection
The classic agent loop asks an LLM “here are 40 tools, which do you call and with what arguments?” That one prompt carries every tool schema, costs real latency, and gets worse as you add tools. Jev agents use a Choice to split the decision from the argument-writing:
def step(transcript, tools):  # tools: what the agent can do this turn
    pick = client.system_one(
        model="jev-latest",
        state=transcript,
        questions={
            "tool": Choice(
                instructions="Which tool should the agent call next?",
                criteria={t.name: t.when_to_use for t in tools},
            ),
        },
    ).answers["tool"]

    if pick.confidence < GATE:                  # tuned on your own traces
        return llm.full_agent_step(transcript)  # the LLM decides this turn
    tool = registry[pick.choice]
    args = llm.fill_arguments(tool.schema, transcript)  # one schema, not forty
    return tool.run(**args)
On this site's tool-selection fixture — a cancelled Berlin flight plus a request to warn the hotel — Jev put all of its probability on search_flights at 0.99 confidence. It picks one step per turn; the loop comes back for the hotel. jev-eval-agent tests the idea at scale: 100 mocked tools, counting the steps an agent needs when the LLM picks the tool and when Jev does, behind a configurable confidence gate.
Pattern 2: a dynamic action space
Tool selection gets more interesting when the options change every turn. A browser agent's action space is whatever is on the page right now — you cannot enumerate it in advance.
jev-ultrafast handles this by indexing the live page into a dynamic action space, then asking Jev to pick both the operation and the target element. A small LLM is invoked only for TYPE_TEXT operations, where actual text has to be written. Everything else — click, scroll, select — never touches a generative model. agent-desktop does the same on a desktop, reading the accessibility tree instead of screenshots so each click is a choice over named controls.
Pattern 3: confidence-gated routing
The cheapest possible agent is one that only wakes the expensive model when it has to. Jev agents use a confidence threshold as the triage layer in front of the LLM:
High confidence
Act directly on Jev's choice. Milliseconds, fractions of a cent.
Middling
Hand to a small or mid-tier LLM with Jev's distribution as a hint.
Low / tie
Escalate to a frontier model or a human. Log it — these are your training signal.
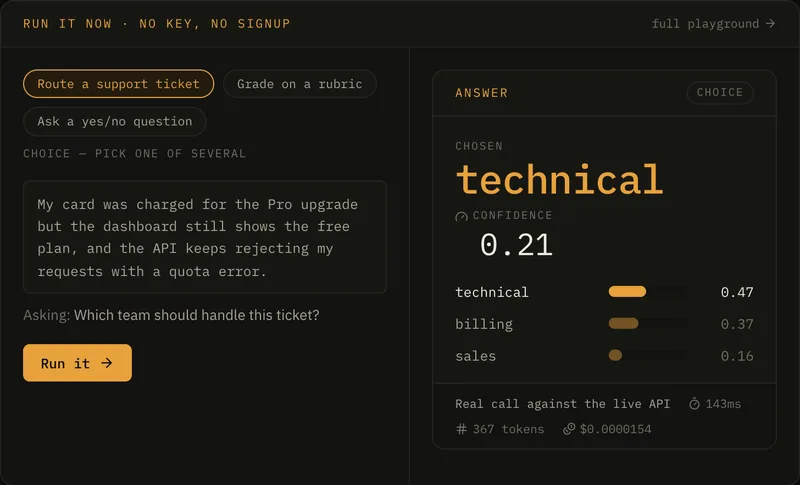
Two details decide whether a gate holds. A Noul carries no confidence field — its probability is the whole answer, so gate on its distance from 0.5. And thresholds do not travel: TypeSafe's failure-mode notes for jev-1.13 show one question asked as a Noul and as a yes/no Choice disagreeing sharply, so tune each gate on the primitive it guards.
Pattern 4: cheap self-checks with Noul
Because questions are evaluated in parallel against one state, verification adds almost no latency. Before an answer goes out, Jev agents use a handful of Noul questions in a single call:
def check(instructions, yes, no):
    return Noul(instructions=instructions,
                criteria=NoulCriteria(true=yes, false=no))

questions = {
    "answers_question": check("Does this answer the user's question?",
                              "Directly addresses the ask", "Evasive or off-topic"),
    "no_pii":           check("Is this free of personal data?",
                              "No names, emails or IDs", "Contains personal data"),
    "tone_ok":          check("Is the tone professional?",
                              "Courteous and appropriate", "Rude or off-brand"),
}
# one call, ~same latency as asking just one
That is measured, not assumed: on the first-party API, four guardrail checks took 81ms of server time and one tool pick 70ms. That fixture's draft named a customer with an email address and guaranteed a refund date; the personal-data check scored 0.01 and the no-promises check 0.06 — two failures before anyone reads it. This used to take a second LLM pass or a pile of regexes.
Pattern 5: stop, continue or ask a human
A familiar agent failure is claiming success it cannot show evidence for. foreman sits above Codex or OpenCode workers and judges whether a job is complete, the tests suffice or a human is needed; Canny checks the tool output, the diff and the test results before a coding agent may say it finished. The core check is two Noul questions:
checks = client.system_one(
    model="jev-latest",
    state=f"TASK: {task}\n\nLAST STEPS: {last_steps}",   # not the whole log
    questions={
        "done": Noul(
            instructions="Is the task finished, with evidence in the last steps?",
            criteria=NoulCriteria(true="Requested change made and verified",
                                  false="Work remains or nothing was verified"),
        ),
        "ask_human": Noul(
            instructions="Does the next step need a human decision?",
            criteria=NoulCriteria(true="Ambiguous requirement or risky action",
                                  false="The agent can safely continue"),
        ),
    },
).answers

if checks["ask_human"].noul >= ASK_AT:
    pause_for_human()
elif checks["done"].noul >= STOP_AT:
    finish()
Send the task and the last few steps, not the transcript: TypeSafe documents that accuracy falls as the state fills with unrelated detail, and a full log soon meets the 32k limit on the state plus the longest question.
Open-source Jev agents worth reading
More public repositories, listed in Built with Jev and on the open-source page:
- jev-codex-router decides, turn by turn in a Codex session, which model answers, how hard it thinks and how fast it runs.
- pi-jev-auto-mode lets Jev decide which actions the Pi coding agent may take without asking.
- jev-browser has an LLM write the plan and Jev make the choice at each step inside it.
- jot bills itself as the first general-purpose System One agent.
To add Jev to an agent you already run, install a skill or an MCP server: TypeSafe's skills package (npx skills add typesafe-ai/skills) teaches an agent the Jev workflow, and typesafe-mcp exposes Choice, Score and Noul to Claude Code, Claude Desktop, Codex and Pi.
Where Jev agents break down
- Arguments still need an LLM. Jev picks; it does not fill in parameters. Your loop needs both models and the plumbing between them.
- Two vendors, two failure modes. A Jev outage now breaks your agent too. Keep an LLM-only fallback path that actually works.
- Thresholds are yours to earn. Measure the cutoff on labelled examples from your own traffic, then pin
jev-1.13.0: thejev-latestalias moves when a release ships. - Text in the state can argue back. Jev reads the state as data, not as an attack, and injected instructions can move its answer. Agents read web pages and tool output, so test every gate against both. The other limits are on limitations.
Jev agents: common questions
How can I use Jev to check whether an agent has finished a task?
Give Jev the original acceptance criteria and evidence of the agent's result, then ask separate Noul questions about each requirement. Your code combines those probabilities and sends uncertain cases for review. Do not use the agent's claim that it finished as the only evidence, and do not treat a positive probability as proof that a test passed.
Source · Checked 2026-10-04
Can Jev run an agent loop on its own?
No. Jev can choose the next tool, but it cannot write that tool's arguments, run the loop or turn a result into prose, so Jev agents pair it with an LLM and ordinary code.
How fast is one decision inside a Jev agent?
TypeSafe quotes 70–500ms end-to-end. Measured on the first-party API, a three-question request took 313ms at the median end to end, and the server's own clock put a one-question tool pick at 70ms. Routing through OpenRouter added about 421ms at the median.