Jev API: how to use it, with the full reference
The Jev API takes one state and any number of typed questions, and returns a probability for every answer. Here is how to call it, and the reference for what comes back.
API
What is the Jev API?
Send a state and typed questions, get typed answers with probabilities. You need a Jev API key from TypeSafe, a gateway or this site; cost is on Jev pricing.
| Endpoint | POST /v1/systemone |
|---|---|
| Price | $0.042 / 1M — input tokens; output free |
| Questions | Choice · Score · Noul |
| Per request | 64k tokens |
Quick answer · verified 2026-10-11
How can I test a Jev API request before integrating it?
Test the decision criteria in the browser playground first, then follow the API request example for the host you intend to use. TypeSafe's first-party API and Jagent's gateway use different keys and request conventions; select the endpoint before copying the request.
Endpoint
Two hosts, same contract. Use TypeSafe's if you have an early-access key. Use ours if you do not, and everything in this Jev API reference applies identically to both.
- Official endpoint
POST https://api.typesafe.ai/v1/systemone- Same shape, our key
POST https://jev-agent.com/api/v1/systemoneField-for-field identical, for a Jev API key from /api-access if you are still on the waitlist. Everything on this page applies to both.- Model routes
jev-latestjev-previewjev-1.13.0- Auth
Authorization: Bearer …— a TypeSafe key for the first host, ajv_live_key for the second. They are not interchangeable, and each host rejects the other's key with a 401.- Context
- 64k tokens
- Modalities
- Text only — no image or audio input at launch
- Latency
- 70–500ms end-to-end
- SDKs
- Python, JavaScript, plus raw HTTP
Your first call
No SDK, no waitlist. A Jev API key from /api-access and plain HTTP:
curl -X POST https://jev-agent.com/api/v1/systemone \
  -H "Authorization: Bearer $JEV_AGENT_KEY" \
  -H "content-type: application/json" \
  -d '{
    "state": "Charged twice for September and cancelling Friday unless refunded.",
    "questions": {
      "route": {
        "type": "choice",
        "instructions": "Which team should handle this?",
        "criteria": { "billing": "Payments and refunds", "technical": "Bugs and outages" }
      },
      "urgency": {
        "type": "noul",
        "instructions": "Does this need a reply today?",
        "criteria": { "true": "Time-sensitive", "false": "Can wait" }
      }
    }
}'{
"model": "jev-1.13.0",
"answers": {
"route": { "type": "choice", "choice": "billing", "confidence": 1,
"probabilities": { "billing": 1, "technical": 0 } },
"urgency": { "type": "noul", "noul": 0.96 }
},
"usage": { "input_tokens": 417, "output_tokens": 69 },
"quota": { "used": 1, "limit": 50, "remaining": 49 }
}The rest of the Jev API reference documents those answer shapes. The same body works against TypeSafe's own host if you hold one of their keys — the two are listed in the card above, and the keys are not interchangeable.
The request model
A request has two parts. The state is what you are asking about: raw text, a transcript, a document, or serialised program state. The questions are what you want decided about it. Every question is evaluated independently, in parallel, against that same state — which is why asking ten questions costs roughly the latency of asking one.
Questions are passed as a dict keyed by an id you choose, and answers come back under those same keys. That is what makes fan-out ergonomic: name the question, read the answer.
Official SDK — needs a TypeSafe key. With a jev-agent key, use the curl above.
{
  "state": "<the text or program state>",
  "questions": {
    "route": {
      "type": "choice",
      "instructions": "Which team should handle this?",
      "criteria": {
        "billing":   "Payments, invoicing, refunds",
        "technical": "Bugs, outages, integrations",
        "sales":     "Pricing, upgrades, new accounts"
      }
    },
    "severity": {
      "type": "score",
      "instructions": "How severe is this?",
      "criteria": ["Low", "Medium", "High", "Critical"]
    },
    "on_topic": {
      "type": "noul",
      "instructions": "Is this about our product?",
      "criteria": { "true": "Clearly about our product", "false": "Unrelated" }
    }
  }
}The three primitives
Choice — Choose an option from a list.
You supply a state and a fixed set of options. Jev returns the winning option key, a probability for every option, and a confidence value — so your code can branch on the winner or fall back when confidence is low.
Returns
choice · probabilities{option} · confidence
Reach for it when
Routing, tool selection, intent classification, triage.
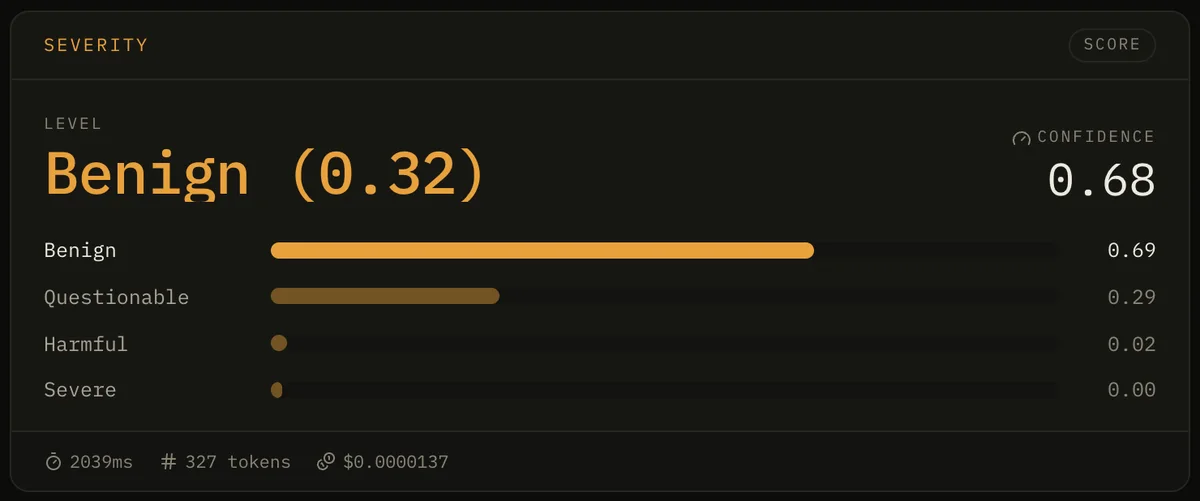
Score — Score the state on a rubric.
You define ordered levels. What comes back is the probability-weighted mean of the level indices, a legend mapping indices to the labels you wrote, and a probability per index.
Returns
score (0..n-1 weighted mean) · legend{index→label} · probabilities{index} · confidence
Reach for it when
Quality grading, ranking, rubric-based evaluation, content moderation tiers.
Noul — Is this statement true?
A single yes/no question that returns the probability of "yes" rather than a hard boolean, letting you pick your own threshold instead of trusting a coin flip.
Returns
noul (0-1 float) — and nothing else
Reach for it when
Boolean gates, guardrails, verification checks, filters.
Three endpoints, one key
On this site one key opens three: /api/v1/systemone takes the body above, /api/v1/classify takes text and one of eight ruleset names, and /api/v1/decisions takes OpenAI's Decisions API request. Rulesets, billing and every error code are in the API docs.
Confidence is the whole point
Choice and Score both return a full probability distribution plus a confidence value, and that is the feature that makes Jev safe to put on a hot path. A traditional classifier hands you a label and shrugs. Jev tells you how sure it is, so you can write the rule your product actually needs:
const res = await fetch("https://jev-agent.com/api/v1/systemone", {
  method: "POST",
  headers: { authorization: `Bearer ${process.env.JEV_AGENT_KEY}`,
             "content-type": "application/json" },
  body: JSON.stringify({ state: ticket, questions: { route: routeQuestion } }),
});
const { answers } = await res.json();

if (answers.route.confidence >= 0.85) {
  dispatch(answers.route.choice);   // fast path: Jev decided
} else {
  escalateToLlm(ticket);            // slow path: not sure enough
}
Response fields follow the primitive: choice and confidence for a choice, score plus legend for a score, noul for a noul, and usage.input_tokens for what it cost.
Pick the threshold empirically against your own labelled data — the right number depends entirely on what a wrong decision costs you.
Model versions this Jev API reference covers
Shapes checked against live responses. The current version is jev-1.13.0, and the model field also takes two aliases:
- jev-latest
- points at
jev-1.13.0. The most recent stable, official release. The default in the client SDKs and in the docs examples. - jev-preview
- points at
jev-1.13.0. The most recent release whether or not it is official. Moves ahead of jev-latest when a preview build exists — there is none right now.
The response carries the versioned ID that actually answered, so you can log which weights produced each result. If you have tuned confidence thresholds against a version, send that version ID instead of an alias and move on your own schedule. On the official host, GET https://api.typesafe.ai/v1/models lists only the aliases, yet the versioned ID is accepted anyway.
What errors and limits does the Jev API have?
A request carries at most 64k tokens, 32k of them for the state plus the longest question, with 255 options per Choice and 10 levels per Score. Past 100,000 tokens or 80 requests a second you get a 429, and an overloaded service returns a 529: retry both with backoff, as TypeSafe's SDKs do by default. Every code we produced, with its fix, is on Jev rate limits and errors.
Documented architectural patterns
Beyond this Jev API reference, TypeSafe's docs describe several composition patterns worth knowing: fan-out (many questions against one state in a single call), routing (a Choice that selects the next handler), and composite scoring (several Score questions combined into an overall judgement). Their cookbook section covers 20+ worked examples including legal analysis, RAG passage classification and entity alignment.
Practical questions
What does Jev Score return, and is it between zero and one?
Score returns the probability-weighted position on the ordered rubric you supplied, plus a legend, per-level probabilities and confidence. With four levels numbered 0 through 3, its range is 0 to 3, not 0 to 1. Noul is the primitive that returns a 0-to-1 probability; mixing these ranges makes thresholds incorrect.
Source · Checked 2026-10-04