Jev open source: the open models and servers around it
Jev itself is closed: TypeSafe publishes no weights, and its hosted API is the only way to call it. What is open is everything around it — models trained to answer the same typed questions, servers that speak the same API, and tools built on the hosted model. On 27 September 2026, two open models scored above Jev 1.13 on the independent JevBench.
Looking for applications built with Jev? Explore the project gallery with screenshots, demo stills and source code, including browser agents, routers and developer tools.
Can you download or self-host Jev? No — these come closest
The Jev open source models and servers you can run yourself. Most answer the same request Jev does.
| Project | What runs, on what | Jev's API |
|---|---|---|
| Plumb-4B | 4B open model; results measured on one RTX 4080 Super | yes, /v1/systemone via jevk5-serve |
| decider | 2B to 35B-A3B open models; the 2B needs about 4 GB of GPU | yes, /v1/systemone |
| Lichen | open weights on local hardware; 93 ms median on a laptop GPU | yes, drop-in |
| OpenJev | DiffusionGemma 26B-A4B on NVIDIA (vLLM) or Apple silicon (MLX) | yes, TypeSafe SDKs unchanged |
| openjev-sglang | Qwen3.6-35B-A3B on one B200, deployable to Modal | yes, TypeSafe HTTP API |
One request, any Jev-compatible endpoint
Jev open source servers speak the same /v1/systemone as Jev. Only the URL and the key change.
curl -X POST http://localhost:8000/v1/systemone \
  -H "content-type: application/json" \
  -d '{
  "model": "jev-latest",
  "state": "Refund request: charged twice for the annual plan, asks for the duplicate back today.",
  "questions": {
    "q": {
      "type": "choice",
      "instructions": "Which team should handle this?",
      "criteria": {
        "billing": "billing",
        "technical": "technical",
        "account": "account"
      }
    }
  }
}'
Jev open source models on JevBench
JevBench is an independent benchmark for Jev-class decision models, run by Benchmark Heaven and not affiliated with TypeSafe. Its score is the harmonic mean of four axes: intelligence, calibration, speed and cost. The top five of v1.4.2.1, published 2026-09-27:
| Model | Weights | Score | Intelligence | Calibration | Speed | Cost |
|---|---|---|---|---|---|---|
| Plumb-4B | open | 65.8 | 53.0 | 75.5 | 93.5 | 55.8 |
| decider-4b v2 | open | 64.1 | 49.4 | 75.0 | 92.9 | 60.9 |
| Jev 1.13.0 | closed | 63.3 | 53.1 | 76.3 | 83.3 | 52.0 |
| Cygnet (Gemma 4 12B) | open | 61.8 | 49.5 | 74.9 | 90.7 | 52.8 |
| Hopper | open | 59.4 | 48.0 | 79.1 | 86.8 | 58.7 |
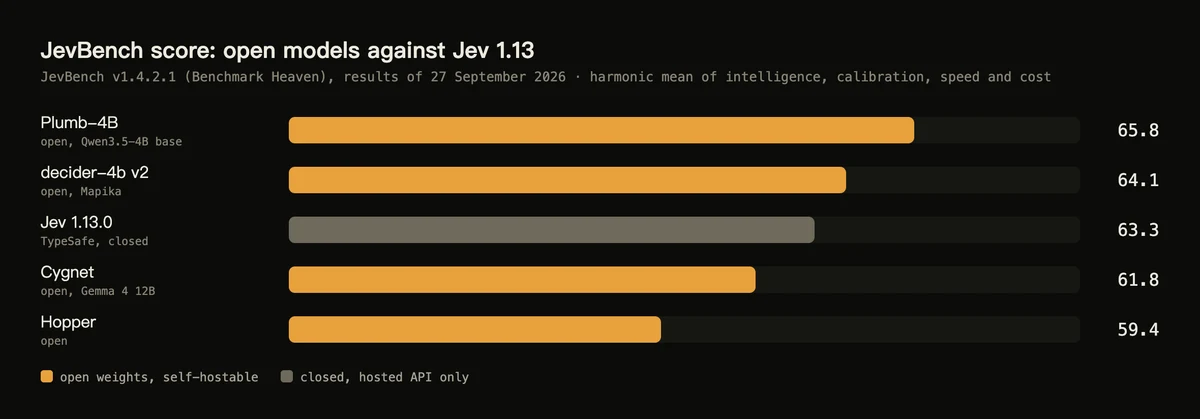
Read the axes, not only the total. The open models win on speed and cost, the two things self-hosting changes. On intelligence Plumb-4B and Jev are level (53.0 against 53.1), and on calibration Jev still leads the top three at 76.3 — how far its stated probabilities can be trusted is still what the hosted model sells. One caution from the benchmark itself: speed for a self-hosted model is its measured latency doubled plus 0.15 seconds, an assumption rather than a measurement. The live board ranks 90 systems.
Self-hosting Jev open source models: what runs, on what
A 3090-class card is enough for the 4B models: SemIf, formerly openjev, targets exactly that, and Plumb-4B's published results come from one RTX 4080 Super. A Mac works too: SemIf scores through PyTorch on Apple Silicon and OpenJev serves through MLX. The larger servers — OpenJev on DiffusionGemma, openjev-sglang on Qwen3.6-35B-A3B — want a data-center GPU, and openjev-sglang deploys to Modal so the GPU only runs while requests arrive. SemIf even runs in a browser, over WebGPU.
The hard part is not the shape of the answer but its calibration: daseinlabs' open-jev found zero-shot Gemma 3 4B over-confident on judgement calls. The trained Jev open source models above close most of that gap, and self-hosting keeps text on your own hardware.
Every Jev open source project we checked
Each one read from its README on 27 September 2026, grouped by what it is.
crh225/plumb
Open modelPlumb-4B: an open one-pass decision model (2 to 16 options, Apache-2.0) trained on teacher-written hard decisions. First on JevBench v1.4.2.1.
Mapika/decider
Open modelOpen System One models fine-tuned from Qwen3.5, 2B to 35B-A3B, Apache-2.0: calibrated probabilities in one forward pass, served on POST /v1/systemone.
NandhaKishorM/laya
Open modelLaya: 421M and 322M encoder checkpoints, Apache-2.0, with a Jev-compatible server.
Mushroom-Systems/lichen
Jev-compatible serverA drop-in local server for /v1/systemone on open weights: 207 of JevBench's 231 public decisions with gemma-4-26B-A4B against 200 for Jev 1.13, by its authors.
razorback16/openjev
Jev-compatible serverA decision server on Jev's wire API, so TypeSafe's SDKs work against it unchanged. DiffusionGemma 26B-A4B through vLLM on NVIDIA or MLX on Apple silicon; questions can also ask about images.
ekzhang/openjev-sglang
Jev-compatible serverThe TypeSafe HTTP API served by Qwen3.6-35B-A3B on SGLang, one B200 per container, deployable to Modal and scaling to zero after five idle minutes.
TheoLeeCJ/SemIf-OpenJev
Open reimplementationSemIf, formerly openjev: typed option probabilities read from an open 4B model, with a WebGPU demo in the browser. Copies the interface, not the model.
daseinlabs/open-jev
Open reimplementationBenchmarks Gemma 3 4B zero-shot against TypeSafe's published Jev numbers and serves a matching /v1/systemone endpoint. Finds Gemma over-confident on judgement calls.
zhihz/openjev
Open reimplementationLocal bilingual (English and Chinese) probability decisions over your own candidate answers, on a frozen Qwen3-4B-Instruct-2507. A research preview that claims no lead over Jev.
JoshuaSP/open-jev
Open reimplementationTyped JSON decisions from DiffusionGemma with no training: 138 of 144 agreement with saved TypeSafe decisions on a customer-voice set, on one H100.
vinnylarouge/jevlike
Open reimplementationAn independently trained starter model with the same input and output shape; its option-attention head can also score controller buttons from image patches.
fstandhartinger/jevbench
BenchmarkJevBench, Benchmark Heaven's independent benchmark for Jev-class decision models: intelligence, calibration, speed and cost, with a live board of 90 ranked systems.
anisselbd/jev-phishing-bench
BenchmarkJev against Claude Haiku 4.5 on 2,000 phishing emails. Jev's raw verdict came out worse, but a logistic regression over five signal questions from the same call reached 95.1%.
themsquared/jev-benchmark
BenchmarkJev on agent tool-call risk classification: accuracy, latency, and whether its confidence is worth routing on.
jkudish/jev-mcp
MCP serverTwelve judgment tools for any MCP client (verify, screen, rerank, classify, review a diff, gate a completion claim), each typed with probabilities in roughly 150 to 500 ms.
dbreunig/building-with-jev-skill
Agent skillA skill for agents writing programs that call Jev: question design, state structure, confidence thresholds, diagnosing wrong answers. Installs into Claude Code, Codex and Cursor.
sutro-sh/jev-align
Criteria optimiserTunes your option descriptions against your own labelled data: it picks the ambiguous rows for you to label, runs GEPA over the labels and shows the proposed wording diff with its score.
andududu/jeview
Developer toolA local gateway and live visualizer: point your client at it and every call is forwarded, kept in SQLite and drawn as it happens. Node 24, no dependencies.
A browser agent where Jev picks the operation and the target element, and a small LLM writes text only when something must be typed.
thruwire/foreman
AgentJev above Codex or OpenCode workers, judging whether a job is complete, requirements are met, tests suffice or a human is needed.
An assistant with 100 mocked tools comparing steps taken when the LLM picks the tool against when Jev does, with confidence-gated routing.
Voice control for a real browser: on every partial transcript, one Jev call answers a dozen typed questions in about 300 ms.
Fish-style zsh autosuggestions, with Jev ranking your last 100 distinct commands against what you are typing.
A Clash Royale bot with no trained policy: vision builds a JSON game state each second, and Jev picks the strategy and the card in about 135 ms.
datawhalechina/jev-cookbook
TutorialIn Chinese, from the Datawhale learning community: Jupyter notebooks from the three question types to 18 worked recipes, a voice-controlled smart home, model evaluation and local fine-tuning. CC BY-NC-SA 4.0.
yibie/awesome-jev
Awesome listThe first curated list of public projects, integrations and discussions built on Jev.
heyjunpenn/awesome-jev
Awesome listA verified catalog of more than 900 open-source projects built with Jev.
yzfly/awesome-jev-zh
Awesome listIn Chinese: official material, SDKs, apps, agent tools, open reproductions and independent evaluations.
Built something that belongs here? The lists at the end of the table index hundreds more, and awesome-jev takes pull requests.
Practical questions
Is Jev open source, and what can I self-host instead?
TypeSafe's Jev is a managed API, not downloadable open weights. Community projects can reproduce its Choice, Score and Noul interface using an open model, but matching the interface does not reproduce Jev's accuracy or confidence. Use the repositories compared on this page, run the same examples on your own data, and measure latency, accuracy and cost before choosing a replacement.
Method and evidence · Checked 2026-10-04