Jev benchmark: what the numbers actually show
Most numbers written about Jev are TypeSafe's own. This Jev benchmark leads with ours — every model through the same eight fixtures on one machine — then the vendor's and other people's, labelled as such.
Our Jev benchmark: eight fixtures, one gateway
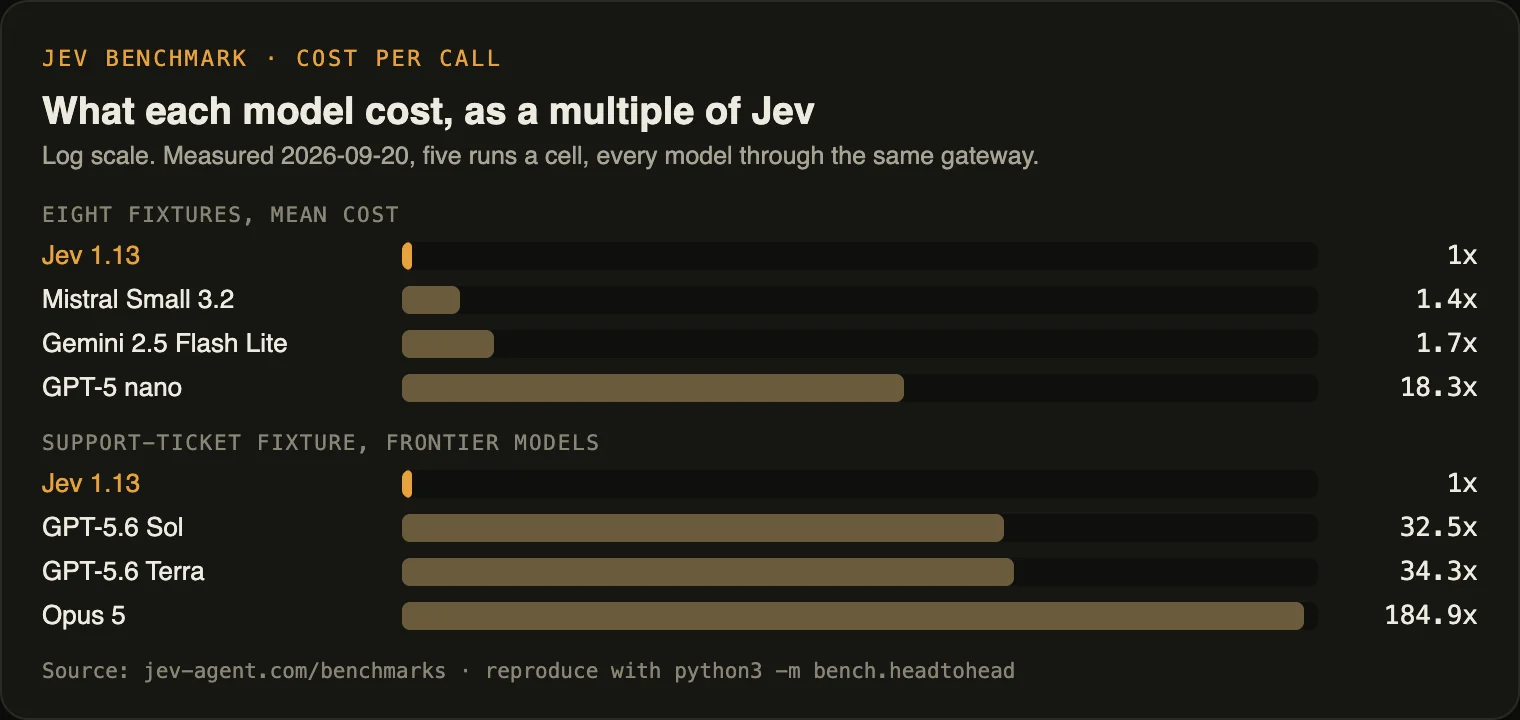
Eight fixtures, 5 runs each, every model through the same gateway on 2026-09-20 — 40 runs per model in total. Reproduce with python3 -m bench.headtohead --repeats 5 from jev-measured.
| Model | Median | Mean cost | vs Jev | Right type |
|---|---|---|---|---|
| Jev 1.13 | 352ms | $0.0000188 | 1x | 40/40 |
| Mistral Small 3.2 | 1,343ms | $0.0000255 | 1.4x | 39/40 |
| Gemini 2.5 Flash Lite | 877ms | $0.0000323 | 1.7x | 37/40 |
| GPT-5 nano | 7,504ms | $0.0003434 | 18.3x | 36/40 |
Correction: the type column was our mistake
We first concluded that chat models return the declared type unreliably: asked for a probability, Gemini answered true on three runs in five and GPT-5 nano returned strings. That was an artifact of how we asked — structured output was off. The identical prompt with response_format: { type: "json_schema", strict: true } as the only change:
| Model | Right type, plain prompt | With json_schema |
|---|---|---|
| Gemini 2.5 Flash Lite | 2/5 | 5/5 |
| GPT-5 nano | 4/5 | 5/5 |
| Mistral Small 3.2 | 5/5 | 5/5 |
What survives. Latency and cost. On the support-ticket fixture with schemas on: Jev 386ms, Gemini 896ms, Mistral 1672ms, GPT-5 nano 7006ms. Cost runs 1.0x, 1.6x, 1.5x and 15x. Those gaps are real and they do not depend on how the prompt was written.
Accuracy: Jev does not win this one
A Jev benchmark that never checks whether answers are right is half a benchmark. So: 27 support tickets whose correct label follows from how the text was written, plus 6 deliberately ambiguous ones with no label, every model 3 times. Measured 2026-09-20 with python3 -m bench.accuracy.
| Model | Correct | Per pass | Confidence, clear | Confidence, ambiguous |
|---|---|---|---|---|
| Jev 1.13 | 27/27 | 27 · 27 · 27 | 0.979 | 0.841 |
| Mistral Small 3.2 | 27/27 | 27 · 27 · 27 | — | — |
| Gemini 2.5 Flash Lite | 26/27 | 26 · 26 · 26 | — | — |
| GPT-5 nano | 26/27 | 26 · 26 · 26 | — | — |
Only Jev produces the confidence columns. Its certainty falls from 0.979 on the clear set to 0.841 on the ambiguous one — the right direction, by a smaller margin than you might hope if you route on a threshold. The chat models return none.
We nearly published a second artifact
At default sampling the chat models changed answers between identical passes (Gemini 26, 25, 26; GPT-5 nano 24, 26, 26). Sending temperature: 0 removes it: every model then scores the same on all three passes, which is the table above.
Limits. Twenty-seven tickets written by us, on one task, in English, three passes each. Enough to retire the claim that Jev is more accurate; not enough to establish that anything else is.
Against the models in TypeSafe's own table
The same Jev benchmark fixture, put to the three frontier models the vendor benchmarks itself against:
| Model | Median | Cost | vs Jev | Right type |
|---|---|---|---|---|
| Jev 1.13 | 358ms | $0.0000226 | 1x | 5/5 |
| GPT-5.6 Sol | 1,545ms | $0.0007360 | 32.5x | 5/5 |
| GPT-5.6 Terra | 1,315ms | $0.0007760 | 34.3x | 5/5 |
| Opus 5 | 4,267ms | $0.0041850 | 184.9x | 0/5 |
Here the multiples are real: 33x and 185x. And the most expensive model was the least compliant: Opus 5 returned every probability as a string, on all five runs.
Five questions cost the same as one
Measured from the server's own clock, via the x-envoy-upstream-service-time header on the first-party API rather than by subtracting an estimated network floor:
| Questions in one request | Fixture | Server time |
|---|---|---|
| 1 | agent-tool-selection | 70ms |
| 3 | lead-scoring | 72ms |
| 4 | agent-output-guardrails | 81ms |
| 5 | phishing-detection | 74ms |
One question takes 70ms of server time; five in the same request take 74ms. “Questions are evaluated in parallel” is a vendor claim everywhere else — this is it read off the server's own header, from the transport comparison.
Per fixture
Median latency per model on each Jev benchmark fixture: the same 8 the use-case pages publish, so a number here traces to code you can read.
| Fixture | Q | Jev 1.13 | GPT-5 nano | Gemini 2.5 Flash Lite | Mistral Small 3.2 |
|---|---|---|---|---|---|
| support-ticket-triage | 3 | 360ms | 7,348ms | 878ms | 1,421ms |
| llm-model-routing | 1 | 346ms | 3,019ms | 860ms | 1,266ms |
| agent-tool-selection | 1 | 347ms | 3,490ms | 856ms | 1,110ms |
| content-moderation | 3 | 365ms | 7,958ms | 877ms | 1,452ms |
| phishing-detection | 5 | 454ms | 10,356ms | 1,003ms | 1,752ms |
| rag-reranking | 1 | 340ms | 4,490ms | 860ms | 1,030ms |
| agent-output-guardrails | 4 | 345ms | 9,354ms | 878ms | 1,707ms |
| lead-scoring | 3 | 356ms | 7,661ms | 892ms | 1,232ms |
The vendor's own Jev benchmark
A custom TypeSafe evaluation across four workflows — security incident response, agent-trace observability, invoice processing and customer service — scoring each model against the average predictions of GPT-6 Astra and Anthropic Fable.
| Model | Accuracy | Cost / case | Latency |
|---|---|---|---|
| Jev | 67.8% | $0.0004 | 0.4s |
| GPT-5.6 Terra | 67.9% | $0.0304–$0.1761 | 10–38s |
| Opus 5 | 73.1% | $0.0304–$0.1761 | 10–38s |
| GPT-5.6 Sol | 74.1% | $0.0304–$0.1761 | 10–38s |
TypeSafe's headline framing: 193.6x faster and 444.6x cheaper than frontier LLMs in peak in-house testing.
Independent Jev benchmark reproductions
Small samples and mostly single authors, but the direction is consistent.
Phishing classification — 2,000 emails vs Claude Haiku 4.5
Jev's raw verdict loses clearly on accuracy against Claude Haiku 4.5 (McNemar p < 0.0001), while winning decisively on speed and cost.
Caveat: Latency was wall-clock measured from a machine in France against US-hosted services.
Passage extraction
Found Jev roughly 25x faster and 580x cheaper than Claude Fable 5.1 — 0.35s versus 8.83s per passage.
Caveat: Speed/cost oriented; not an accuracy study.
LLM model routing
Replacing an LLM classifier with Jev's Choice primitive was faster than either original configuration and significantly cheaper.
Caveat: Used one sample per tier, so it is not an accuracy verification and says little about borderline cases.
Agent tool-call risk classification
A reproducible harness measuring Jev on tool-call risk classification, including whether the confidence score is worth routing on.
Caveat: Measures Jev alone — provider adapters exist but no API key was available, so comparison columns are empty. The author explicitly states it neither supports nor refutes the vendor multipliers.
The most useful finding so far
In the phishing benchmark Jev's one-shot verdict lost to Claude Haiku 4.5, but five signal questions in the same call, combined by a plain logistic regression, reached 95.1% accuracy. Haiku asked the same five questions did about as well, so the lesson is the method: query broadly and combine the answers yourself.
How to read any Jev benchmark
- Check what accuracy means. Agreement with other models is not ground truth.
- Check where latency was measured from. The phishing benchmark timed France to US endpoints: real network, not model against model.
- Check the sample size. The routing test used one sample per tier. Directional, not conclusive.
- Check whether a comparison actually ran. The tool-call risk harness has empty comparison columns; its author says so.
- Then run your own. On your data, the answer may differ.