Jev API documentation: calling the API with your key
Three endpoints, one key, one balance. Everything in this Jev API documentation works with the key you get on this site, and none of it needs an SDK.
Authentication
A bearer token on every request — every example in this Jev API documentation reads it from $JEV_AGENT_KEY. Get one at /api-access — no card, no waitlist — and manage it on your dashboard.
Authorization: Bearer jv_live_…
Keys are stored hashed and shown once; a lost key cannot be recovered, so create another. Up to five at a time, so staging and production revoke independently.
POST /api/v1/systemone
Your own questions, in the official shape: the request and answer formats in TypeSafe's Jev API documentation apply unchanged.
curl -X POST https://jev-agent.com/api/v1/systemone \
  -H "Authorization: Bearer $JEV_AGENT_KEY" \
  -H "content-type: application/json" \
  -d '{
    "state": "Charged twice for September and cancelling Friday unless refunded.",
    "questions": {
      "queue": {
        "type": "choice",
        "instructions": "Which team should handle this?",
        "criteria": { "billing": "Payments and refunds", "technical": "Bugs and outages" }
      },
      "severity": {
        "type": "score",
        "instructions": "How urgent is this?",
        "criteria": ["Low", "Normal", "High", "Urgent"]
      },
      "churn": {
        "type": "noul",
        "instructions": "Threatening to cancel?",
        "criteria": { "true": "Yes", "false": "No" }
      }
    }
  }'
model is optional: jev-latest by default (Jev 1.14 since late October), jev-preview, jev-1.14.0, jev-1.13.0, or any decision model id from GET /api/v1/models.
Three answer shapes that catch people out
scoreis not 0–1. It is the probability-weighted mean of the rubric indices, so it runs 0..n−1:2.48on a four-level rubric means “between High and Urgent”.- Score probabilities are keyed by index, as strings —
"0","1"— never by your label. Uselegendto map back. - A
noulhas noconfidencefield. Not null — absent. Distance from 0.5 is what you have.
POST /api/v1/classify
Text plus a ruleset name. No question shapes to write, no model to choose.
curl -X POST https://jev-agent.com/api/v1/classify \
  -H "Authorization: Bearer $JEV_AGENT_KEY" \
  -H "content-type: application/json" \
  -d '{
    "ruleset": "support-ticket-triage",
    "items": ["Charged twice for September and cancelling Friday unless refunded."]
}'{
"ruleset": "support-ticket-triage",
"ruleset_version": 1,
"model": "jev-1.13.0",
"results": [
{ "index": 0,
"model": "jev-1.13.0",
"answers": {
"queue": { "type": "choice", "choice": "billing", "confidence": 1 },
"severity": { "type": "score", "score": 2.48, "legend": {"0":"Low","3":"Urgent"} },
"churn_risk": { "type": "noul", "noul": 0.97 }
},
"latency_ms": 333 }
],
"usage": { "credits_charged": 1, "used": 1, "limit": 5, "remaining": 4 }
}Up to 20 items per request; failures are reported per item, not for the whole batch.
The rulesets
| id | What it decides | Questions |
|---|---|---|
| support-ticket-triage | Route an inbound ticket to a queue, grade its urgency, and flag churn risk. | 3 |
| llm-model-routing | Decide how much model capability a request actually needs, before you spend it. | 1 |
| agent-tool-selection | Pick which tool an agent should call next from a fixed toolset. | 1 |
| content-moderation | Grade harm on a four-band rubric and flag targeting and spam separately. | 3 |
| phishing-detection | Independent yes/no signals for an email — combine them yourself rather than trusting one verdict. | 5 |
| rag-reranking | Score a retrieved passage for real relevance, not embedding similarity. | 1 |
| agent-output-guardrails | Verification checks on a draft response before it reaches a user. | 4 |
| lead-scoring | Score fit and intent against a rubric so hot leads reach a human today. | 3 |
The exact Jev call behind each one is public at GET /api/v1/rulesets/<id>, no key required, so any ruleset can move to your own TypeSafe key whenever you like.
POST /api/v1/decisions
OpenAI's Decisions API request for Jev or any of the 13 decision models: set the OpenAI SDK's baseURL to https://jev-agent.com/api/v1. model defaults to jev-latest.
curl -X POST https://jev-agent.com/api/v1/decisions \
  -H "Authorization: Bearer $JEV_AGENT_KEY" \
  -H "content-type: application/json" \
  -d '{"input": "Charged twice for September and cancelling Friday unless refunded.",
       "questions": [
         {"type": "choice", "name": "queue", "instructions": "Which team should handle this?",
          "choices": [{"value": "billing"}, {"value": "technical"}]},
{"type": "predicate", "name": "churn", "instructions": "The customer threatens to cancel."}]}'{
"model": "jev-latest",
"answers": [
{ "type": "choice", "name": "queue", "choice": "billing", "confidence": 1,
"probabilities": [{"value": "billing", "probability": 1}, {"value": "technical", "probability": 0}] },
{ "type": "predicate", "name": "churn", "probability": 0.96 }
],
"usage": { "input_tokens": 348, "output_tokens": 0, "total_tokens": 348, "…": "…" },
"quota": { "charged": 1, "credits_per_1k_input_tokens": 1, "…": "…" }
}Answers keep the question order; an unanswerable one is a refusal. Only quota is ours. input_image data URLs work on the four image models; text-only models return a 400. Limits per model are on decision models.
State
state is what you are asking about: one per request, read by every question, so all three types can share a call. It can also be a JSON object or an array of text values, and an object is usually better, because each part gets a name.
{
  "state": {
    "ticket": { "subject": "Duplicate charge", "text": "Charged twice for order A-104." },
    "order": { "id": "A-104", "charges": [ { "usd": 49 }, { "usd": 49 } ] },
    "refund_policy": "Duplicate charges are eligible for a refund."
  },
  "questions": { "…": "…" }
}
That is one state holding a ticket, an order and a policy. Jev reads text on this endpoint (TypeSafe's image input is still experimental and is not switched on here; images go to an image model through /api/v1/decisions), and its accuracy is best in English.
Confidence, and what to do with it
Confidence is not the winning probability: a two-option choice split 51/49 has a clear winner and very little certainty. Act unattended above a threshold, hand the rest to a person or an LLM, and pick the threshold against your own labelled data — our own measurements put easy inputs at about 0.98 and genuinely ambiguous ones at 0.84.
What a call costs
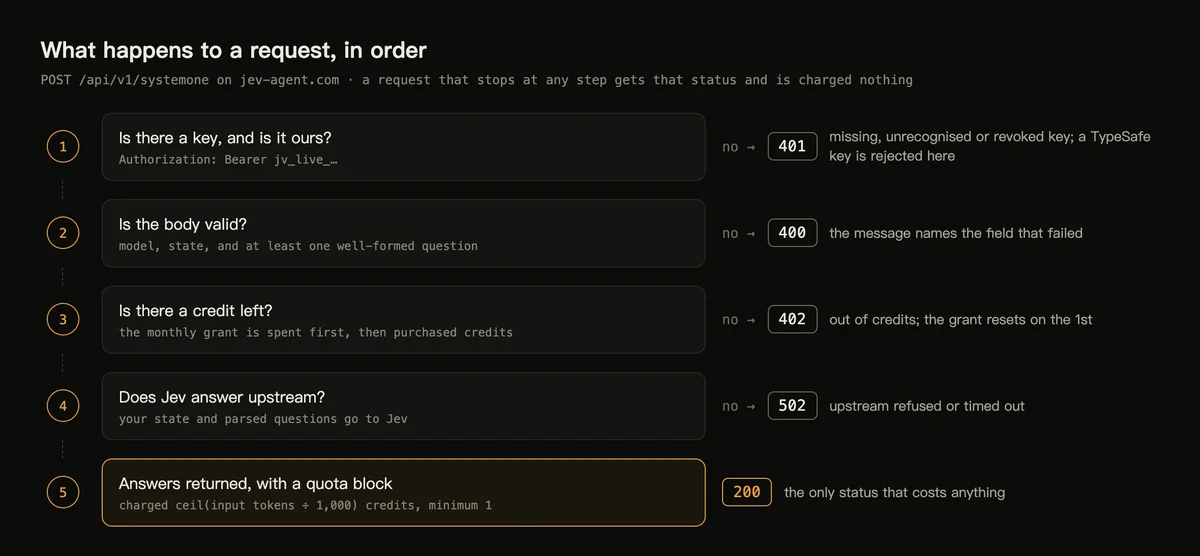
One credit is 1,000 input tokens. A request costs ceil(input_tokens / 1,000) with a floor of one, charged per request rather than per question — questions share the state and the state is nearly all of the tokens. Pricier decision models scale with their price: 2.4 credits per 1,000 tokens for GPT-6 Luna, 5.8 for Clef.
Your own TypeSafe key. Add X-TypeSafe-Key: <your TypeSafe key> next to Authorization and Jev runs on your TypeSafe account: TypeSafe bills you, 0 credits are charged, and the key is used for that call only, never stored. If TypeSafe refuses it, you get that error, not our key.
| What you send | Input tokens | Credits |
|---|---|---|
| A support ticket, three questions | ~540 | 1 |
| A page of documentation | ~1,800 | 2 |
| 20 tickets through /classify in one call | ~10,800 | 11 |
Every account gets 5 credits a month, spent before anything you have bought. Purchased credits never expire, and a failed request costs nothing. Top up or check GET /api/keys with your key for the current balance.
Limits
There is no per-minute limit at any tier: usage is counted in credits. Each request follows Jev's own ceilings, and /api/v1/systemone checks what it can before calling: 255 options per Choice and 2 to 10 Score levels. The token budget, 64k per request and 32k for the state plus the longest question, is checked upstream; all three come back as 400s that say what to change.
/api/v1/classify does have batch limits, because batching is ours rather than anything the official API defines: 20 items per request, 50 with credits. Full table on the credits page.
Errors
| 400 | A malformed body, or a request the model refuses, such as one over the token budget. The message says which; sending `kind` instead of `type` lands here. |
| 401 | Missing, unrecognised or revoked key. A TypeSafe key will not work on this host, and vice versa. |
| 402 | Out of credits. The monthly grant resets on the 1st; top-ups do not expire. |
| 404 | A model id /api/v1/decisions does not serve; the body lists the valid ones. |
| 502 | The model was unavailable on both routes, or timed out. Nothing is charged; retry with backoff. |
| 503 | Our key store or the API is unavailable. Nothing is charged. |
Every error is {"error": "…"} with a sentence you can act on (OpenAI's error object on /api/v1/decisions); a 400 on an unknown ruleset lists the valid ones, and a 402 carries your balance. Retry only 502 and 503, with backoff; the rest fail the same way twice. Calling api.typesafe.ai directly returns different codes, listed with fixes on Jev rate limits and errors.
Managing keys from code
curl https://jev-agent.com/api/keys      -H "Authorization: Bearer $JEV_AGENT_KEY"   # usage
curl -X PUT    https://jev-agent.com/api/keys -H "Authorization: Bearer $JEV_AGENT_KEY"   # rotate
curl -X DELETE https://jev-agent.com/api/keys -H "Authorization: Bearer $JEV_AGENT_KEY"   # revoke
Rotating kills the old key at once and returns a new one; usage follows the account, not the key.