Jev limitations: when not to use it
Jev is genuinely good at a narrow thing. This page is the other half — the limits, the failure modes, and the one claim that is weaker than it first reads. None of it is secret; most of it is just not the vendor's job to tell you.
When should I not use Jev?
Scope: this is about Jev by TypeSafe AI — the System One decision model that returns Choice / Score / Noul answers, not free-form text.
Do not use it when: you need a sentence (summaries, chat, code, explanations); the answer set cannot be enumerated before the request; data cannot leave your network; you already have tens of thousands of labels for one narrow task (a fine-tuned classifier usually wins on accuracy and cost); or you want a single oracle verdict with an audit-ready rationale.
Do use it when: the answer is a decision from a set you already know — routing, tool pick, rubric score, yes/no gates — especially on a hot path where a full LLM round-trip hurts. Its edge shows up when you ask several cheap questions in one call and combine them yourself, not when you query it once like a chat model.
| Which Jev | TypeSafe AI's decision model — not unrelated products or acronyms that also say JEV |
|---|---|
| Skip if you need | prose, chat, code, summaries — Jev generates no text at all |
| Skip if options | cannot be listed up front — Choice only picks from the set you send |
| Skip if data | cannot leave your network — closed weights; no VPC / self-host / air-gap |
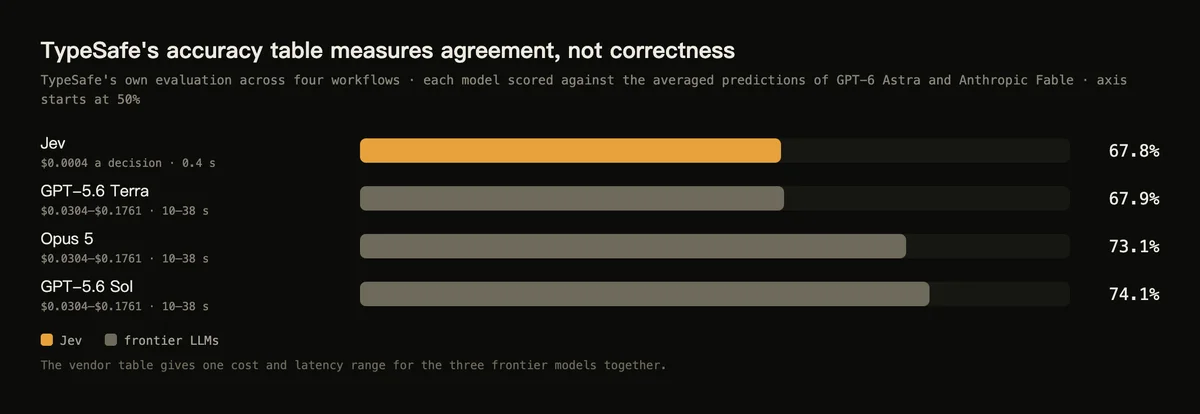
| Vendor accuracy | 67.8% — below GPT-5.6 Sol 74.1% and Opus 5 73.1% on TypeSafe's own table; agreement, not ground truth |
| Independent H2H | lost to Claude Haiku 4.5 — 2,000 phishing emails, McNemar p < 0.0001 — won on speed and cost; five signals + logistic regression reached 95.1% |
Quick answer · verified 2026-09-19
Jev limitations that prompting will not change
Each of the Jev limitations below comes from what the model is, not from how you ask it.
It writes nothing
No prose, no code, no summaries, no free-form anything. If your feature ends in text, you still need an LLM and now you are running two models.
Options are fixed per request
Choice picks from the set you send. It cannot propose an option you did not think of, so a genuinely open-ended question has no good encoding.
Text only
Text only — no image or audio input at launch Screenshots, documents as images and audio all need something in front.
64k tokens per request
And a tighter 32k ceiling on the state plus your longest single question. Long transcripts and big documents need chunking or retrieval first — and accuracy drops well before the limit does, because irrelevant state is a distractor.
Closed weights, hosted only
No self-hosting, no VPC, no air-gap. If your data cannot leave your network, Jev is out — see the open reimplementations instead.
Not OpenAI-compatible
No messages array, no choices[0].message.content. You cannot repoint an existing OpenAI SDK at it; you need a bespoke client.
The accuracy claim is weaker than it reads
Of the Jev limitations on this page, this is the one worth slowing down on, because the headline numbers invite a conclusion the data does not support.
TypeSafe's published evaluation scores Jev at 67.8% — essentially tied with GPT-5.6 Terra (67.9%), and several points below GPT-5.6 Sol (74.1%) and Opus 5 (73.1%). So even the vendor is not claiming accuracy leadership; the claim is comparable accuracy at radically better cost and latency.
The strongest independent test so far ran 2,000 phishing emails against Claude Haiku 4.5 and found Jev's single verdict statistically worse (McNemar p < 0.0001), while winning decisively on speed and cost. The same study found the fix: five cheap signal questions in one call, combined in a plain logistic regression, reached 95.1% accuracy — though a two-line regex scored 91.6% on the same emails, and Claude Haiku asked the same five questions did about as well. Treat Jev as a signal generator you query broadly, not an oracle you query once.
Operational things that will bite you
None of the Jev limitations in this section live in the model's weights. They show up when you run it in production:
- You will not find it in a model picker. Jev's modality is
text->decisionswith an emptysupported_parameters, so gateway catalogues built for chat models filter it out. Searching a gateway for “jev” can return nothing while the model is live. Address it by exact id. - Confidence thresholds are yours to earn. A winning option at 0.34 confidence is a coin flip with extra steps. Copying a threshold off a blog post — including this site — instead of measuring it on your own labelled data is the most common way to ship a bad router.
- Two vendors, two outages. Adding Jev to an LLM pipeline means either can take you down. Keep an LLM-only fallback that is actually exercised, not just written.
- Latency depends on where you are. The quoted 70–500ms end-to-end is end-to-end from somewhere close. From a machine far from the host the network floor alone can exceed 200ms before the model does anything — measure your own round trip before promising a number.
- Launch pricing is not a contract. TypeSafe has said it cannot prove the price is not subsidised, while expecting prices to fall. Model your unit economics with headroom.
- Access is still gated. First-party keys go out in batches. Gateways carry it today, but then their billing, limits and privacy terms apply instead.
Cases where it is simply the wrong tool
Open-ended extraction where you cannot enumerate the answers. Anything that must produce a human-readable explanation alongside the decision. Workloads under a strict data-residency rule. Tasks where a fine-tuned classifier on your own labelled data would win outright — if you have 50,000 labelled examples of exactly one task, a small trained model will likely beat a general decision model on both accuracy and cost.
In these cases, none of the Jev limitations is something to engineer around. The job belongs to a different tool.
Common questions about Jev limitations
Can Jev still make wrong decisions even with high confidence?
Yes. Constraining the answer set prevents answers outside your options, but it does not guarantee the selected option is correct. Evaluate confidence thresholds on labeled examples from your own workload, record confident mistakes, and retain an uncertain or other option plus a review path.
Source · Checked 2026-10-04
Can Jev replace my LLM?
No. Jev produces no text at all — no summaries, no code, no conversation. It replaces the decision steps inside a pipeline, not the writing. Most real systems run both.
Is Jev more accurate than a frontier LLM?
Not on the evidence available. TypeSafe's own table puts Jev at 67.8%, below GPT-5.6 Sol (74.1%) and Opus 5 (73.1%), and that figure measures agreement with other frontier models rather than correctness against ground truth. One independent head-to-head found Jev's raw verdict statistically worse than Claude Haiku 4.5.
Can I self-host Jev?
No. There are no open weights and no VPC or on-premises option. Community projects reimplement the interface with open models, but they are not Jev and their calibration is their own.
Can Jev handle images or audio?
Not at launch. Text input only.